stein雅虎社区
雅虎社区 时间:2021-02-18 阅读:()
Cross-LanguageUrdu-English(CLUE)TextAlignmentCorpusNotebookforPANatCLEF2015IsrarHanif,RaoMuhammadAdeelNawab,AfffaArbab,HumaJamshed,SaraRiaz,andEhsanUllahMunirDepartmentofComputerScience,COMSATSInstituteofInformationTechnology(Wah&LahoreCampuses),Pakistan.
aoaisrar@bzu.
edu.
pk,adeelnawab@ciitlahore.
edu.
pk,nagrah2012@gmail.
com,humaj62@gmail.
com,sarariaz15@gmail.
com,ehsanmunir@comsats.
edu.
pkAbstractPlagiarismiswellknownproblemoftheday.
Easyaccesstoprintandelectronicmediaandreadytousematerialmadeiteasytoreusetheexistingtextinnewdocument.
Theseverityoftheproblemismuchreducedinmonolingualcontextbytheautomatedandtailoredeffortmadebytheresearchcommunitybuttheissueisyetnotproperlyaddressedincrosslanguage(CL)textreuse.
AnystoryorarticlewritteninanysourcelanguagelikeUrduissimplytranslatedintargetlanguagelikeEnglishandtranslatorclaimsitashisown.
Availabilityofstandardandsimulatedresourceaddresstheissueandactastestbedforanalyzingandimplementingavailableplagiarismdetectionapproaches.
Theresearchworkisaimedatenrichingtheavailablecross-languagecorpusandontheotherhandprovidingabenchmarkcorpustoCrossLanguagePlagiarism(CLP)domain.
1IntroductionTextreuseistheprocessofdevelopinganewdocumentusingthedataofexistingdoc-uments.
Plagiarismisamostfamiliartypeoftextreuse.
Ingeneral,plagiarismiscon-sideredasreuseofthoughts,procedures,outcomes,orwordswithoutclearlyshowingtheoriginalsource.
Thesizeoftextthatisreusedvariesfromcasetocase.
Insomecon-ditionsauthorsuseonlyphrases,sentencesorpassagestocreatenewdocumentwhileinsomeconditions,wordbyworddocumentisreusedtocreateanewdocument.
Tocreateanewdocumentdatacanbecollectedfromdifferentsourcedocuments.
Insomeconditionsentiredocumentoforiginaltextisreusedtocreatenewdocument.
Possiblewaystodetectplagiarismare(1)IntrinsicPlagiarismDetection-indicatingwhetherallpassageswrittenbysingleauthorand(2)ExtrinsicPlagiarismDetection-pointingallsourcesfromwherepassagesareusedtocreatethesuspiciousdocument[18].
PlagiarismhascrossedthelanguageboundariesnowlikeUrdutoEnglishorany.
Translationaltechnologiesaregivingnewwaysofplagiarism,knownascrosslanguageplagiarism(CLP).
Incrosslanguageplagiarism,sourcematerialistranslatedfromonelanguagetoanotherandthentranslateddataisreusedtodevelopanewdocumentwith-outgivingreferencesoftheoriginalsource.
Generallysuchunattributedtextreuseisalsolabeledasplagiarism[8].
InthistypeofplagiarismonlylanguagechangeoccurssuchasfromUrdutoEnglishorviceversa.
That'swhycrosslanguageplagiarismisalsocalledtranslationplagiarism.
Barron-CedenoalsodenesCLPasapieceoftextinonelanguagetranslatedintoatargetlanguagewhilekeepingthecontentandsemanticssamewithoutreferringtheorigin[2].
AvailabilityofreadytousedataindifferentformatsandinmultiplelanguagesoninternetisalsoboostingthecaseofCLP.
Studentassignments,andnewspaperstoriesandarticlesarehotdomainsforCLPaseducationandinformationhasnobarriersandboundaries.
CLPneedstodevelopabenchmarkcorpushavingsourceandtargetlan-guagedocumentpairstodetectanylevelofplagiarism.
Urduisalanguagewithmorethan100millionnativespeakers1.
Fewcorpusesaredevelopedforcross-languageinformationretrieval(CLIR)[7]butnoseriousefforthasbeenmadetoaddressCLPproblem.
Englishisanofcialandalmosteducationallanguageinindo-Pakregion.
ThisdiversityraisedtheCLPissueswithmorepotentialinthisregionespeciallyinhighereducationsector[6].
ThereforedevelopinganUrdu-EnglishcorporaforCLPdetectionismuchneededareatobefocused.
ThisresearchisaimedatgeneratingastandardcorpusinUrdu-Englishlanguagepairs.
ThecorpuswillserveasbaseforCLPdetectionandanalyzingmultipleeval-uationtechniquesincontextofperformance.
Threelevelsofplagiarism(NearCopy,LightRevision,andHeavyRevision)enabledittodetectplagiarismatdifferentlevels.
Automatedandmanualefforttogeneratesuspiciousdocumentmadethecorpusmorerealisticandprecise.
Therestofthepaperisorganizedasfollows.
Section2summarizestherelatedwork.
Section3describescorpusgenerationprocessindetail.
Analysisaboutcorpusispresentedinsection4.
Finally,section5concludesthepaper.
2RelatedWorkGenerationofcorpususingsimulatedandarticialapproachasrecommendedbyPot-thastetal.
isinpracticenow[16].
CloughandStevensonin2011createdashortanswercorpuswhichcontainsplagiarizedexamplesgeneratedbasedonsimulatedformat[4].
Similareffortwasmadebysteinetal.
forPAN-PC-09[17]andbyPotthastetal.
forPAN-PC-10corpus[9].
Inspiteofthefactthatresearchcommunityisaddressingtheplagiarismissuepo-tentially,itismajorlyyetlimitedtomonolingualaspect.
TheminoreffortmadeincrosslingualaspectoftheproblemisalsolimitedtofewEuropeanlanguageslikeSpanishandGermanassourceandEnglishassuspiciousinsource-suspiciouslanguagepairs.
DifferentcrosslingualcorporalikeEnglish-Spanish[19]andEnglish-Germancor-pus[10][12][15][13][14]andmanyothershavebeendevelopedfordetectionandanalysisinthisdomain.
NewPAN@FIREtaskslike(CL!
NSS)isanefforttotracesimilarnewsstoriesacrossthelanguages[5].
In2009,EuropeanCommissionsofceforofcialpublications(OPOCE)createdacorpusforcrosslanguageresearch.
Cross-LanguageIndianTextReuseCompetitioncorpusisastandardcorpusinEnglish-Hindilanguagepairperspective[1].
Wikipediaarticleswereselectedassourceincomputerscienceandtourismwith112documentsassourceand276suspiciousdocumentsfordifferentlevelsofplagiarizedfragments.
Alongwithcorpuscreation,applyingplagia-rismdetectionapproachesonnewlycreatedandalreadyavailablecorpusesisalsoinpractice.
TheJRC-AcquisMultilingualParallelCorpuswasusedbyPotthastetal.
toapplyCLPdetectionapproaches.
23,564documents,extractedfromlegaldocumentsofEuropeanUnion,incorporatethecorpus[11].
Outof22languagesinlegaldocumentcollection,only5includingFrench,Germen,Polish,DutchandSpanishwasselectedtogeneratesource-suspiciouslanguagepairwithEnglishlanguageassource.
Compara-bleWikipediaCorpusisanotherexampleofexperimentingwithsimilarapproach.
Thecorpuscontains45,984documents.
ApplyingCLPdetectionapproachesonmultiplecorporahavealsobeendonebyCeskaetal.
[3].
TwocorpusesJRC-EUandFairy-taleCorpuswereusedforthepur-pose.
JRC-EUcomposedof400documentsrandomlyextractedfromlegislationreportsofEuropeanUnion.
Outthese400documents,200wereinEnglishassourceandre-maining200wereinCzech.
Fairy-taleCorpuswith54documentsoutofwhich27inEnglishand27inCzechtranslatedfromEnglish,wasthepartofexperiment.
3CorpusGenerationProcessForthePAN2015TextAlignmenttask,wesubmittedacross-languagecorpus(Urdu-Englishlanguagepair)forevaluatingtheperformanceofCLPdetectionsystem.
TheCLUEcorpuscontainssimulatedcasesofplagiarism(sourcefragmentsareinEnglishandsuspiciousonesinEnglish).
3.
1GenerationofSource-SuspiciousFragmentPairsTogeneratesource-suspiciousfragmentpairs,wecollectedsourcetextsfromtwodo-mains:(1)computerscienceand(2)generalessaytopics.
AllthesourcefragmentswerecollectedfromWikipedia(http://ur.
wikipedia.
org/wiki/urduinfootnote).
Itislikelythattheamountoftextreusedforplagiarizemayvaryfromaphrase,sentence,paragraphtoentiredocument.
Therefore,thesourcefragmentsweredividedintothreecategories:(1)small(lessthan50words),(2)medium(50-100words)and(3)large(100-200)words.
Table1showsthedistributionofsource-suspiciousfragmentParis.
Togeneratesimulatedcasesofplagiarismparticipants(volunteers),whowereuni-versitystudents(undergraduateandpostgraduate)wereaskedtorewritethesourcefrag-ment(inUrdu)togeneratetheplagiarizedfragment(inEnglish)usingoneofthethreemethods.
i.
NearCopy:Participantsweretoldtoautomaticallytranslatethesourcefragmenttogeneratetheplagiarizedfragment.
ii.
LightRevision:Usingthisapproach,theplagiarizedfragmentwascreatedintwosteps.
Intherststepsourcefragment(inUrdu)isautomaticallytranslatedintoEnglish.
Inthesecondstep,thetranslatedfragmentispassedthroughanautomatictextrewritingtoolcalledArticleRewriter1togeneratetheplagiarizedfragment(i.
e.
lightrevisionofthesourcefragment).
iii.
HeavyRevision:Participantswereinstructednottousetheautomaticmachinetranslationtoolsforgeneratingheavyrevisionofthesourcetext.
Instead,theywereaskedtomanuallytranslatetheoriginalsourcetextinsuchawaythatitlookslikeaparaphrasedcopyofthesourcetext.
Leveloffragments(words)(Approx.
)LevelnameNooffragments(270)CS(180)GL(90)50and=100and<=200Essay(Large)3015Table1.
Statisticsofsource-suspiciousfragmentpairsusedintheproposedcorpus3.
2DocumentCollectionandCorpusCompositionTheproposedcorpuscontainstotal1000documents(500sourcedocuments(inUrdu)and500suspiciousdocuments(inEnglish)).
Allthedocumentsinthecorpusarecol-lectedfromfreelyavailableonlineresources.
Adocumentinthecorpusbelongstothedomainofcomputerscienceorgeneraltopics.
Computersciencetopics(Total50)mainlyincludes:Freesoftware,OpenSource,BinaryNumbers,DatabaseNormaliza-tion,Articialintelligence,Robotics,MobileApps,Yahoo,MSN,Google,Whatsapp,Android,twitter,Facebook,RUBYlanguage,Gmail,Skype,Dailymotion,HTMLandfewothers.
Generaldomaintopicswerealsosameincountandmainlyinclude:Globalwarming,MuhammadIqbal,Capitalism,Bookselling,Mosque,PakistanAirForce,Two-Nationtheory,Cricket,Fashion,Capitalism,LahoreForte,BadshahiMasjid,Glob-alizationandfewothers.
Outof500suspiciousdocuments,270areplagiarizedandremaining230arenon-plagiarized.
Onlyonesource-plagiarizedfragmentpairwasin-sertedintoonesource-suspiciousdocumentpair.
Computersciencesource-plagiariesfragmentpairswereinsertedintocomputersciencesource-suspiciousdocumentsandsimilarlysource-plagiarizedfragmentpairsongeneraltopicswereinsertedintosource-suspiciousdocumentpairswhichbelongedtothedomainofgeneraltopics.
Outof270source-plagiarizedfragmentpairs,180arefromComputerSciencedo-mainand90fromGeneraltopicsdomain.
Allthesource-plagiarizedfragmentpairswererandomlyinsertedintosource-sus-piciousdocumentpairs.
4AnalysisandDiscussionThedevelopedcorpusisdividedintosourceandsuspiciousdocuments.
AlthoughthemanualrevisionisdoneoneachsourcefragmenttogenerateitsNC,LRandHRver-sionbuttheorderofsentenceswaskeptsame.
Manualrevisionwasdonetoovercomeissuesgeneratedbyautomatictranslationtoolsoutcome.
ProvidingSource(Urdu)ver-siontoparticipantforgeneratingitsHeavyRevision(HR)madetheplagiarizedtextmorerealistic.
5ConclusionThepaperdescribesthecorpuscreationprocessfordetectionofplagiarismincrosslanguagedomainofUrdu-Englishpairs.
Thecorpuscanbeusedasbenchmarkortestbedforupcomingtasksofperformanceevaluationamongdifferentplagiarismdetectiontechniques.
Infutureweintendtoincreasethesizeofcorpus.
6PeerReviewFollowingdatasetswereobservedandmostofthexmlfeaturesincludinglengthandoffsetofthefragmentinsertedinsourceandsuspiciousdocumentswerefoundcorrectinalldatasets.
Amismatchwasalsofoundinfewcasesduetonewlineandsomespe-cialcharacters.
Datasetwiseotherndingsaredescribedas:–cheema15-training-dataset-englishDifferentfoldersareusedtoconsidercasesofplagiarismatundergrad,MasterandPh.
Dlevels.
Fragmentsareinsertedatcharacterlevelatrandomplaces.
Sourcetosuspiciousratioisontooneassinglesourcefragmentisusedtomakeadocumentsuspicious.
ObfuscationstrategyisalmostparaphrasingwithgoodqualityPairEntry/ExampleType/Articial/SimulatedQualityofPlagiarismsuspicious-document0099-source-document0391.
xmlSimulatedWellparaphrasedsuspicious-document0259-source-document0189.
xmlSimulatedGoodsuspicious-document0309-source-document0321.
xmlSimulatedWellparaphrasedsuspicious-document0386-source-document0186.
xmlSimulatedWellparaphrasedsuspicious-document0485-source-document0447.
xmlSimulatedNEARCOPY–palkovskii15-training-dataset-englishMultilingualfeaturesalthoughdescribedbutobfuscationislimitedtoEnglishonly.
Fragmentsareinsertedatwordlevelatrandomplacesinsuspiciousdocument.
Sourceandsuspiciousdocumentsareoflargesizeandfromgeneraldomain.
PairEntry/ExampleType/Articial/SimulatedQualityofPlagiarismsuspicious-document00021-source-document02467.
xmlArticialNEARCOPYsuspicious-document00067-source-document02563.
xmlArticialNEARCOPYsuspicious-document00081-source-document03075.
xmlArticialNEARCOPYsuspicious-document00380-source-document00270.
xmltranslation-chainNEARCOPYsuspicious-document00407-source-document02140.
xmltranslation-chainNEARCOPY–mohtaj15-training-dataset-englishMultiplefragmentsareinsertedinsingledocumentatrandomplaces.
Inmostofthecases3fragmentsareinsertedatcharacterlevel.
Placementoffragmentsisatrandomplacesinsourceandsuspiciousdocuments.
Althoughinfewcasesfrag-mentsinsourceandsuspiciousdocumentswerefoundirrelevantbutdatasetiswellcomposedoverall.
Largesizeddocumentsfromgeneraldomainareused.
PairEntry/ExampleType/Articial/SimulatedQualityofPlagiarismsuspicious-document110926-source-document307308.
xmlArticialNEARCOPYsuspicious-document179883-source-document517709.
xmlArticialNEARCOPYsuspicious-document235057-source-document534046.
xmlArticialNEARCOPYsuspicious-document102450-source-document106487.
xmlArticialPoorsuspicious-document405184-source-document26685.
xmlSimulatedGoodsuspicious-document105415-source-document149775.
xmlArticialGoodsuspicious-document157936-source-document198805.
xmlSimulatedGood–kong15-training-dataset-chineseSametextisusedtosuspectmanydocuments.
Smallsizeddatasetwithonly4suspiciousand78sourcedocuments.
Suspicioustextisinsertedatconsecutivelo-cationsprobablyatcharacterlevel.
BothsourceandsuspiciousdocumentsareinChinesebutdocumentsalsohavelargeEnglishtextinfewcases.
Qualityofplagia-rismcannotbejudged.
–khoshnava15-training-dataset-persianAdatasetwith720suspiciousand802sourcedocuments.
Almostone-to-onesourcetosuspiciousratioisthere.
Articialtypeofplagiarismcaseswithnoob-fuscationstrategymostly.
BothsourceandsuspiciousdocumentsareinPersianthereforequalityofplagiarismcannotbejudged.
–Asghari15-training-dataset-english-persianLargedatasetwith15959sourceand5470suspiciousdocuments.
MostofthePlagiarismcasesarearticiallygenerated.
DuetoEnglishtoPersiannaturequalityofplagiarismcannotbejudgedproperly.
Formationofdatasetisne.
–alvi15-training-dataset-englishAdatasetwith70sourceand90suspiciousdocuments.
Threetypesofobfusca-tionstrategiesareused:charactersubstitution,synonymreplacementandhumanretelling.
Onesourcefragmentisusedindifferentobfuscationstrategiestosuspectthesuspiciousdocument.
Insertionisatsentencelevelandalmostnearcopyorexactcopyofsourcefragmentisusedinsuspiciousdocuments.
Thereissomedif-ferenceinthesourcelength,sourceoffset,suspiciouslengthandsuspiciousoffsetbecauseofnewlinecharacter.
PairEntry/ExampleType/Articial/SimulatedQualityofPlagiarismsuspicious-document00003.
txtsource-document00002.
txtRetellingGoodsuspicious-document00043-source-document00018.
xmlRetellingGoodsuspicious-document00102-source-document00040.
xmlRetellingGoodsuspicious-document00128-source-document00078.
xmlAutomaticWellparaphrasedsuspicious-document00039-source-document00010.
xmlcharacter-substitutionGoodsuspicious-document00078-source-document00020.
xmlcharacter-substitutionWellparaphrasedsuspicious-document00099-source-document00025.
xmlcharacter-substitutionWellparaphrasedAcknowledgementsWearethankfultoallvolunteersfortheirvaluablecontributioninconstructionofthiscorpus.
References1.
Barrón-Cedeno,A.
,Rosso,P.
,Devi,S.
L.
,Clough,P.
,Stevenson,M.
:Pan@re:Overviewofthecross-language!
ndiantextre-usedetectioncompetition.
In:MultilingualInformationAccessinSouthAsianLanguages,pp.
59–70.
Springer(2013)2.
Barrón-Cedeno,A.
,Rosso,P.
,Pinto,D.
,Juan,A.
:Oncross-lingualplagiarismanalysisusingastatisticalmodel.
In:PAN(2008)3.
Ceska,Z.
,Toman,M.
,Jezek,K.
:Multilingualplagiarismdetection.
In:ArticialIntelligence:Methodology,Systems,andApplications,pp.
83–92.
Springer(2008)4.
Clough,P.
,Stevenson,M.
:Developingacorpusofplagiarisedshortanswers.
LanguageResourcesandEvaluation45(1),5–24(2011)5.
Gupta,P.
,Clough,P.
,Rosso,P.
,Stevenson,M.
:Pan@re:Overviewofthecross-language!
ndiannewsstorysearch(cl!
nss)track.
In:ForumforInformationRetrievalEvaluation,ISI,Kolkata,India(2012)6.
Judge,G.
:Plagiarism:Bringingeconomicsandeducationtogether(withalittlehelpfromit).
ComputersinHigherEducationEconomicsReviews(Virtualedition)20,21–26(2008)7.
Littman,M.
L.
,Dumais,S.
T.
,Landauer,T.
K.
:Automaticcross-languageinformationretrievalusinglatentsemanticindexing.
In:Cross-languageinformationretrieval,pp.
51–62.
Springer(1998)8.
Martin,B.
:Plagiarism:amisplacedemphasis.
JournalofInformationEthics3(2),36–47(1994)9.
Potthast,M.
,Barrón-Cedeo,A.
,Eiselt,A.
,Stein,B.
,Rosso,P.
:Overviewofthe2ndinternationalcompetitiononplagiarismdetection.
In:CLEF(NotebookPapers/LABs/Workshops)(2010)10.
Potthast,M.
,Barrón-Cedeo,A.
,Eiselt,A.
,Stein,B.
,Rosso,P.
:Overviewofthe3rdinternationalcompetitiononplagiarismdetection.
In:NotebookPapersofCLEF11LabsandWorkshops(2011)11.
Potthast,M.
,Barrón-Cedeo,A.
,Stein,B.
,Rosso,P.
:Cross-languageplagiarismdetection.
LanguageResourcesandEvaluation45(1),45–62(2011)12.
Potthast,M.
,Gollub,T.
,Hagen,M.
,Kiesel,J.
,Michel,M.
,Oberllander,A.
,Tippmann,M.
,Barrón-Cedeo,A.
,Gupta,P.
,Rosso,P.
:Overviewofthe4thinternationalcompetitiononplagiarismdetection.
In:CLEF(OnlineWorkingNotes/Labs/Workshop)(2012)13.
Potthast,M.
,Gollub,T.
,Rangel,F.
,Rosso,P.
,Stamatatos,E.
,Stein,B.
:ImprovingthereproducibilityofpanAZssharedtasks.
In:InformationAccessEvaluation.
Multilinguality,Multimodality,andInteraction,pp.
268–299.
Springer(2014)14.
Potthast,M.
,Hagen,M.
,Beyer,A.
,Busse,M.
,Tippmann,M.
,Rosso,P.
,Stein,B.
:Overviewofthe6thinternationalcompetitiononplagiarismdetection.
In:CLEF(OnlineWorkingNotes/Labs/Workshop)(2013)15.
Potthast,M.
,Hagen,M.
,Gollub,T.
,Tippmann,M.
,Kiesel,J.
,Rosso,P.
,Stamatatos,E.
,Stein,B.
:Overviewofthe5thinternationalcompetitiononplagiarismdetection.
In:CLEF(OnlineWorkingNotes/Labs/Workshop)(2013)16.
Potthast,M.
,Stein,B.
,Barrón-Cedeo,A.
,Rosso,P.
:Anevaluationframeworkforplagiarismdetection.
In:Proceedingsofthe23rdinternationalconferenceoncomputationallinguistics:Posters.
pp.
997–1005.
AssociationforComputationalLinguistics(2010)17.
Potthast,M.
,Stein,B.
,Eiselt,A.
,Barrón-Cedeo,A.
,Rosso,P.
:Overviewofthe1stInternationalCompetitiononPlagiarismDetection.
In:Stein,B.
,Rosso,P.
,Stamatatos,E.
,Koppel,M.
,Agirre,E.
(eds.
)SEPLN09WorkshoponUncoveringPlagiarism,Authorship,andSocialSoftwareMisuse(PAN09).
pp.
1–9.
CEUR-WS.
org(Sep2009),http://ceur-ws.
org/Vol-50218.
Stein,B.
,zuEissen,S.
M.
,Potthast,M.
:Strategiesforretrievingplagiarizeddocuments.
In:Proceedingsofthe30thannualinternationalACMSIGIRconferenceonResearchanddevelopmentininformationretrieval.
pp.
825–826.
ACM(2007)19.
Stein,B.
,Rosso,P.
,Stamatatos,E.
,Koppel,M.
,Agirre,E.
:3rdpanworkshoponuncoveringplagiarism,authorshipandsocialsoftwaremisuse.
In:25thAnnualConferenceoftheSpanishSocietyforNaturalLanguageProcessing(SEPLN).
pp.
1–77(2009)
aoaisrar@bzu.
edu.
pk,adeelnawab@ciitlahore.
edu.
pk,nagrah2012@gmail.
com,humaj62@gmail.
com,sarariaz15@gmail.
com,ehsanmunir@comsats.
edu.
pkAbstractPlagiarismiswellknownproblemoftheday.
Easyaccesstoprintandelectronicmediaandreadytousematerialmadeiteasytoreusetheexistingtextinnewdocument.
Theseverityoftheproblemismuchreducedinmonolingualcontextbytheautomatedandtailoredeffortmadebytheresearchcommunitybuttheissueisyetnotproperlyaddressedincrosslanguage(CL)textreuse.
AnystoryorarticlewritteninanysourcelanguagelikeUrduissimplytranslatedintargetlanguagelikeEnglishandtranslatorclaimsitashisown.
Availabilityofstandardandsimulatedresourceaddresstheissueandactastestbedforanalyzingandimplementingavailableplagiarismdetectionapproaches.
Theresearchworkisaimedatenrichingtheavailablecross-languagecorpusandontheotherhandprovidingabenchmarkcorpustoCrossLanguagePlagiarism(CLP)domain.
1IntroductionTextreuseistheprocessofdevelopinganewdocumentusingthedataofexistingdoc-uments.
Plagiarismisamostfamiliartypeoftextreuse.
Ingeneral,plagiarismiscon-sideredasreuseofthoughts,procedures,outcomes,orwordswithoutclearlyshowingtheoriginalsource.
Thesizeoftextthatisreusedvariesfromcasetocase.
Insomecon-ditionsauthorsuseonlyphrases,sentencesorpassagestocreatenewdocumentwhileinsomeconditions,wordbyworddocumentisreusedtocreateanewdocument.
Tocreateanewdocumentdatacanbecollectedfromdifferentsourcedocuments.
Insomeconditionsentiredocumentoforiginaltextisreusedtocreatenewdocument.
Possiblewaystodetectplagiarismare(1)IntrinsicPlagiarismDetection-indicatingwhetherallpassageswrittenbysingleauthorand(2)ExtrinsicPlagiarismDetection-pointingallsourcesfromwherepassagesareusedtocreatethesuspiciousdocument[18].
PlagiarismhascrossedthelanguageboundariesnowlikeUrdutoEnglishorany.
Translationaltechnologiesaregivingnewwaysofplagiarism,knownascrosslanguageplagiarism(CLP).
Incrosslanguageplagiarism,sourcematerialistranslatedfromonelanguagetoanotherandthentranslateddataisreusedtodevelopanewdocumentwith-outgivingreferencesoftheoriginalsource.
Generallysuchunattributedtextreuseisalsolabeledasplagiarism[8].
InthistypeofplagiarismonlylanguagechangeoccurssuchasfromUrdutoEnglishorviceversa.
That'swhycrosslanguageplagiarismisalsocalledtranslationplagiarism.
Barron-CedenoalsodenesCLPasapieceoftextinonelanguagetranslatedintoatargetlanguagewhilekeepingthecontentandsemanticssamewithoutreferringtheorigin[2].
AvailabilityofreadytousedataindifferentformatsandinmultiplelanguagesoninternetisalsoboostingthecaseofCLP.
Studentassignments,andnewspaperstoriesandarticlesarehotdomainsforCLPaseducationandinformationhasnobarriersandboundaries.
CLPneedstodevelopabenchmarkcorpushavingsourceandtargetlan-guagedocumentpairstodetectanylevelofplagiarism.
Urduisalanguagewithmorethan100millionnativespeakers1.
Fewcorpusesaredevelopedforcross-languageinformationretrieval(CLIR)[7]butnoseriousefforthasbeenmadetoaddressCLPproblem.
Englishisanofcialandalmosteducationallanguageinindo-Pakregion.
ThisdiversityraisedtheCLPissueswithmorepotentialinthisregionespeciallyinhighereducationsector[6].
ThereforedevelopinganUrdu-EnglishcorporaforCLPdetectionismuchneededareatobefocused.
ThisresearchisaimedatgeneratingastandardcorpusinUrdu-Englishlanguagepairs.
ThecorpuswillserveasbaseforCLPdetectionandanalyzingmultipleeval-uationtechniquesincontextofperformance.
Threelevelsofplagiarism(NearCopy,LightRevision,andHeavyRevision)enabledittodetectplagiarismatdifferentlevels.
Automatedandmanualefforttogeneratesuspiciousdocumentmadethecorpusmorerealisticandprecise.
Therestofthepaperisorganizedasfollows.
Section2summarizestherelatedwork.
Section3describescorpusgenerationprocessindetail.
Analysisaboutcorpusispresentedinsection4.
Finally,section5concludesthepaper.
2RelatedWorkGenerationofcorpususingsimulatedandarticialapproachasrecommendedbyPot-thastetal.
isinpracticenow[16].
CloughandStevensonin2011createdashortanswercorpuswhichcontainsplagiarizedexamplesgeneratedbasedonsimulatedformat[4].
Similareffortwasmadebysteinetal.
forPAN-PC-09[17]andbyPotthastetal.
forPAN-PC-10corpus[9].
Inspiteofthefactthatresearchcommunityisaddressingtheplagiarismissuepo-tentially,itismajorlyyetlimitedtomonolingualaspect.
TheminoreffortmadeincrosslingualaspectoftheproblemisalsolimitedtofewEuropeanlanguageslikeSpanishandGermanassourceandEnglishassuspiciousinsource-suspiciouslanguagepairs.
DifferentcrosslingualcorporalikeEnglish-Spanish[19]andEnglish-Germancor-pus[10][12][15][13][14]andmanyothershavebeendevelopedfordetectionandanalysisinthisdomain.
NewPAN@FIREtaskslike(CL!
NSS)isanefforttotracesimilarnewsstoriesacrossthelanguages[5].
In2009,EuropeanCommissionsofceforofcialpublications(OPOCE)createdacorpusforcrosslanguageresearch.
Cross-LanguageIndianTextReuseCompetitioncorpusisastandardcorpusinEnglish-Hindilanguagepairperspective[1].
Wikipediaarticleswereselectedassourceincomputerscienceandtourismwith112documentsassourceand276suspiciousdocumentsfordifferentlevelsofplagiarizedfragments.
Alongwithcorpuscreation,applyingplagia-rismdetectionapproachesonnewlycreatedandalreadyavailablecorpusesisalsoinpractice.
TheJRC-AcquisMultilingualParallelCorpuswasusedbyPotthastetal.
toapplyCLPdetectionapproaches.
23,564documents,extractedfromlegaldocumentsofEuropeanUnion,incorporatethecorpus[11].
Outof22languagesinlegaldocumentcollection,only5includingFrench,Germen,Polish,DutchandSpanishwasselectedtogeneratesource-suspiciouslanguagepairwithEnglishlanguageassource.
Compara-bleWikipediaCorpusisanotherexampleofexperimentingwithsimilarapproach.
Thecorpuscontains45,984documents.
ApplyingCLPdetectionapproachesonmultiplecorporahavealsobeendonebyCeskaetal.
[3].
TwocorpusesJRC-EUandFairy-taleCorpuswereusedforthepur-pose.
JRC-EUcomposedof400documentsrandomlyextractedfromlegislationreportsofEuropeanUnion.
Outthese400documents,200wereinEnglishassourceandre-maining200wereinCzech.
Fairy-taleCorpuswith54documentsoutofwhich27inEnglishand27inCzechtranslatedfromEnglish,wasthepartofexperiment.
3CorpusGenerationProcessForthePAN2015TextAlignmenttask,wesubmittedacross-languagecorpus(Urdu-Englishlanguagepair)forevaluatingtheperformanceofCLPdetectionsystem.
TheCLUEcorpuscontainssimulatedcasesofplagiarism(sourcefragmentsareinEnglishandsuspiciousonesinEnglish).
3.
1GenerationofSource-SuspiciousFragmentPairsTogeneratesource-suspiciousfragmentpairs,wecollectedsourcetextsfromtwodo-mains:(1)computerscienceand(2)generalessaytopics.
AllthesourcefragmentswerecollectedfromWikipedia(http://ur.
wikipedia.
org/wiki/urduinfootnote).
Itislikelythattheamountoftextreusedforplagiarizemayvaryfromaphrase,sentence,paragraphtoentiredocument.
Therefore,thesourcefragmentsweredividedintothreecategories:(1)small(lessthan50words),(2)medium(50-100words)and(3)large(100-200)words.
Table1showsthedistributionofsource-suspiciousfragmentParis.
Togeneratesimulatedcasesofplagiarismparticipants(volunteers),whowereuni-versitystudents(undergraduateandpostgraduate)wereaskedtorewritethesourcefrag-ment(inUrdu)togeneratetheplagiarizedfragment(inEnglish)usingoneofthethreemethods.
i.
NearCopy:Participantsweretoldtoautomaticallytranslatethesourcefragmenttogeneratetheplagiarizedfragment.
ii.
LightRevision:Usingthisapproach,theplagiarizedfragmentwascreatedintwosteps.
Intherststepsourcefragment(inUrdu)isautomaticallytranslatedintoEnglish.
Inthesecondstep,thetranslatedfragmentispassedthroughanautomatictextrewritingtoolcalledArticleRewriter1togeneratetheplagiarizedfragment(i.
e.
lightrevisionofthesourcefragment).
iii.
HeavyRevision:Participantswereinstructednottousetheautomaticmachinetranslationtoolsforgeneratingheavyrevisionofthesourcetext.
Instead,theywereaskedtomanuallytranslatetheoriginalsourcetextinsuchawaythatitlookslikeaparaphrasedcopyofthesourcetext.
Leveloffragments(words)(Approx.
)LevelnameNooffragments(270)CS(180)GL(90)50and=100and<=200Essay(Large)3015Table1.
Statisticsofsource-suspiciousfragmentpairsusedintheproposedcorpus3.
2DocumentCollectionandCorpusCompositionTheproposedcorpuscontainstotal1000documents(500sourcedocuments(inUrdu)and500suspiciousdocuments(inEnglish)).
Allthedocumentsinthecorpusarecol-lectedfromfreelyavailableonlineresources.
Adocumentinthecorpusbelongstothedomainofcomputerscienceorgeneraltopics.
Computersciencetopics(Total50)mainlyincludes:Freesoftware,OpenSource,BinaryNumbers,DatabaseNormaliza-tion,Articialintelligence,Robotics,MobileApps,Yahoo,MSN,Google,Whatsapp,Android,twitter,Facebook,RUBYlanguage,Gmail,Skype,Dailymotion,HTMLandfewothers.
Generaldomaintopicswerealsosameincountandmainlyinclude:Globalwarming,MuhammadIqbal,Capitalism,Bookselling,Mosque,PakistanAirForce,Two-Nationtheory,Cricket,Fashion,Capitalism,LahoreForte,BadshahiMasjid,Glob-alizationandfewothers.
Outof500suspiciousdocuments,270areplagiarizedandremaining230arenon-plagiarized.
Onlyonesource-plagiarizedfragmentpairwasin-sertedintoonesource-suspiciousdocumentpair.
Computersciencesource-plagiariesfragmentpairswereinsertedintocomputersciencesource-suspiciousdocumentsandsimilarlysource-plagiarizedfragmentpairsongeneraltopicswereinsertedintosource-suspiciousdocumentpairswhichbelongedtothedomainofgeneraltopics.
Outof270source-plagiarizedfragmentpairs,180arefromComputerSciencedo-mainand90fromGeneraltopicsdomain.
Allthesource-plagiarizedfragmentpairswererandomlyinsertedintosource-sus-piciousdocumentpairs.
4AnalysisandDiscussionThedevelopedcorpusisdividedintosourceandsuspiciousdocuments.
AlthoughthemanualrevisionisdoneoneachsourcefragmenttogenerateitsNC,LRandHRver-sionbuttheorderofsentenceswaskeptsame.
Manualrevisionwasdonetoovercomeissuesgeneratedbyautomatictranslationtoolsoutcome.
ProvidingSource(Urdu)ver-siontoparticipantforgeneratingitsHeavyRevision(HR)madetheplagiarizedtextmorerealistic.
5ConclusionThepaperdescribesthecorpuscreationprocessfordetectionofplagiarismincrosslanguagedomainofUrdu-Englishpairs.
Thecorpuscanbeusedasbenchmarkortestbedforupcomingtasksofperformanceevaluationamongdifferentplagiarismdetectiontechniques.
Infutureweintendtoincreasethesizeofcorpus.
6PeerReviewFollowingdatasetswereobservedandmostofthexmlfeaturesincludinglengthandoffsetofthefragmentinsertedinsourceandsuspiciousdocumentswerefoundcorrectinalldatasets.
Amismatchwasalsofoundinfewcasesduetonewlineandsomespe-cialcharacters.
Datasetwiseotherndingsaredescribedas:–cheema15-training-dataset-englishDifferentfoldersareusedtoconsidercasesofplagiarismatundergrad,MasterandPh.
Dlevels.
Fragmentsareinsertedatcharacterlevelatrandomplaces.
Sourcetosuspiciousratioisontooneassinglesourcefragmentisusedtomakeadocumentsuspicious.
ObfuscationstrategyisalmostparaphrasingwithgoodqualityPairEntry/ExampleType/Articial/SimulatedQualityofPlagiarismsuspicious-document0099-source-document0391.
xmlSimulatedWellparaphrasedsuspicious-document0259-source-document0189.
xmlSimulatedGoodsuspicious-document0309-source-document0321.
xmlSimulatedWellparaphrasedsuspicious-document0386-source-document0186.
xmlSimulatedWellparaphrasedsuspicious-document0485-source-document0447.
xmlSimulatedNEARCOPY–palkovskii15-training-dataset-englishMultilingualfeaturesalthoughdescribedbutobfuscationislimitedtoEnglishonly.
Fragmentsareinsertedatwordlevelatrandomplacesinsuspiciousdocument.
Sourceandsuspiciousdocumentsareoflargesizeandfromgeneraldomain.
PairEntry/ExampleType/Articial/SimulatedQualityofPlagiarismsuspicious-document00021-source-document02467.
xmlArticialNEARCOPYsuspicious-document00067-source-document02563.
xmlArticialNEARCOPYsuspicious-document00081-source-document03075.
xmlArticialNEARCOPYsuspicious-document00380-source-document00270.
xmltranslation-chainNEARCOPYsuspicious-document00407-source-document02140.
xmltranslation-chainNEARCOPY–mohtaj15-training-dataset-englishMultiplefragmentsareinsertedinsingledocumentatrandomplaces.
Inmostofthecases3fragmentsareinsertedatcharacterlevel.
Placementoffragmentsisatrandomplacesinsourceandsuspiciousdocuments.
Althoughinfewcasesfrag-mentsinsourceandsuspiciousdocumentswerefoundirrelevantbutdatasetiswellcomposedoverall.
Largesizeddocumentsfromgeneraldomainareused.
PairEntry/ExampleType/Articial/SimulatedQualityofPlagiarismsuspicious-document110926-source-document307308.
xmlArticialNEARCOPYsuspicious-document179883-source-document517709.
xmlArticialNEARCOPYsuspicious-document235057-source-document534046.
xmlArticialNEARCOPYsuspicious-document102450-source-document106487.
xmlArticialPoorsuspicious-document405184-source-document26685.
xmlSimulatedGoodsuspicious-document105415-source-document149775.
xmlArticialGoodsuspicious-document157936-source-document198805.
xmlSimulatedGood–kong15-training-dataset-chineseSametextisusedtosuspectmanydocuments.
Smallsizeddatasetwithonly4suspiciousand78sourcedocuments.
Suspicioustextisinsertedatconsecutivelo-cationsprobablyatcharacterlevel.
BothsourceandsuspiciousdocumentsareinChinesebutdocumentsalsohavelargeEnglishtextinfewcases.
Qualityofplagia-rismcannotbejudged.
–khoshnava15-training-dataset-persianAdatasetwith720suspiciousand802sourcedocuments.
Almostone-to-onesourcetosuspiciousratioisthere.
Articialtypeofplagiarismcaseswithnoob-fuscationstrategymostly.
BothsourceandsuspiciousdocumentsareinPersianthereforequalityofplagiarismcannotbejudged.
–Asghari15-training-dataset-english-persianLargedatasetwith15959sourceand5470suspiciousdocuments.
MostofthePlagiarismcasesarearticiallygenerated.
DuetoEnglishtoPersiannaturequalityofplagiarismcannotbejudgedproperly.
Formationofdatasetisne.
–alvi15-training-dataset-englishAdatasetwith70sourceand90suspiciousdocuments.
Threetypesofobfusca-tionstrategiesareused:charactersubstitution,synonymreplacementandhumanretelling.
Onesourcefragmentisusedindifferentobfuscationstrategiestosuspectthesuspiciousdocument.
Insertionisatsentencelevelandalmostnearcopyorexactcopyofsourcefragmentisusedinsuspiciousdocuments.
Thereissomedif-ferenceinthesourcelength,sourceoffset,suspiciouslengthandsuspiciousoffsetbecauseofnewlinecharacter.
PairEntry/ExampleType/Articial/SimulatedQualityofPlagiarismsuspicious-document00003.
txtsource-document00002.
txtRetellingGoodsuspicious-document00043-source-document00018.
xmlRetellingGoodsuspicious-document00102-source-document00040.
xmlRetellingGoodsuspicious-document00128-source-document00078.
xmlAutomaticWellparaphrasedsuspicious-document00039-source-document00010.
xmlcharacter-substitutionGoodsuspicious-document00078-source-document00020.
xmlcharacter-substitutionWellparaphrasedsuspicious-document00099-source-document00025.
xmlcharacter-substitutionWellparaphrasedAcknowledgementsWearethankfultoallvolunteersfortheirvaluablecontributioninconstructionofthiscorpus.
References1.
Barrón-Cedeno,A.
,Rosso,P.
,Devi,S.
L.
,Clough,P.
,Stevenson,M.
:Pan@re:Overviewofthecross-language!
ndiantextre-usedetectioncompetition.
In:MultilingualInformationAccessinSouthAsianLanguages,pp.
59–70.
Springer(2013)2.
Barrón-Cedeno,A.
,Rosso,P.
,Pinto,D.
,Juan,A.
:Oncross-lingualplagiarismanalysisusingastatisticalmodel.
In:PAN(2008)3.
Ceska,Z.
,Toman,M.
,Jezek,K.
:Multilingualplagiarismdetection.
In:ArticialIntelligence:Methodology,Systems,andApplications,pp.
83–92.
Springer(2008)4.
Clough,P.
,Stevenson,M.
:Developingacorpusofplagiarisedshortanswers.
LanguageResourcesandEvaluation45(1),5–24(2011)5.
Gupta,P.
,Clough,P.
,Rosso,P.
,Stevenson,M.
:Pan@re:Overviewofthecross-language!
ndiannewsstorysearch(cl!
nss)track.
In:ForumforInformationRetrievalEvaluation,ISI,Kolkata,India(2012)6.
Judge,G.
:Plagiarism:Bringingeconomicsandeducationtogether(withalittlehelpfromit).
ComputersinHigherEducationEconomicsReviews(Virtualedition)20,21–26(2008)7.
Littman,M.
L.
,Dumais,S.
T.
,Landauer,T.
K.
:Automaticcross-languageinformationretrievalusinglatentsemanticindexing.
In:Cross-languageinformationretrieval,pp.
51–62.
Springer(1998)8.
Martin,B.
:Plagiarism:amisplacedemphasis.
JournalofInformationEthics3(2),36–47(1994)9.
Potthast,M.
,Barrón-Cedeo,A.
,Eiselt,A.
,Stein,B.
,Rosso,P.
:Overviewofthe2ndinternationalcompetitiononplagiarismdetection.
In:CLEF(NotebookPapers/LABs/Workshops)(2010)10.
Potthast,M.
,Barrón-Cedeo,A.
,Eiselt,A.
,Stein,B.
,Rosso,P.
:Overviewofthe3rdinternationalcompetitiononplagiarismdetection.
In:NotebookPapersofCLEF11LabsandWorkshops(2011)11.
Potthast,M.
,Barrón-Cedeo,A.
,Stein,B.
,Rosso,P.
:Cross-languageplagiarismdetection.
LanguageResourcesandEvaluation45(1),45–62(2011)12.
Potthast,M.
,Gollub,T.
,Hagen,M.
,Kiesel,J.
,Michel,M.
,Oberllander,A.
,Tippmann,M.
,Barrón-Cedeo,A.
,Gupta,P.
,Rosso,P.
:Overviewofthe4thinternationalcompetitiononplagiarismdetection.
In:CLEF(OnlineWorkingNotes/Labs/Workshop)(2012)13.
Potthast,M.
,Gollub,T.
,Rangel,F.
,Rosso,P.
,Stamatatos,E.
,Stein,B.
:ImprovingthereproducibilityofpanAZssharedtasks.
In:InformationAccessEvaluation.
Multilinguality,Multimodality,andInteraction,pp.
268–299.
Springer(2014)14.
Potthast,M.
,Hagen,M.
,Beyer,A.
,Busse,M.
,Tippmann,M.
,Rosso,P.
,Stein,B.
:Overviewofthe6thinternationalcompetitiononplagiarismdetection.
In:CLEF(OnlineWorkingNotes/Labs/Workshop)(2013)15.
Potthast,M.
,Hagen,M.
,Gollub,T.
,Tippmann,M.
,Kiesel,J.
,Rosso,P.
,Stamatatos,E.
,Stein,B.
:Overviewofthe5thinternationalcompetitiononplagiarismdetection.
In:CLEF(OnlineWorkingNotes/Labs/Workshop)(2013)16.
Potthast,M.
,Stein,B.
,Barrón-Cedeo,A.
,Rosso,P.
:Anevaluationframeworkforplagiarismdetection.
In:Proceedingsofthe23rdinternationalconferenceoncomputationallinguistics:Posters.
pp.
997–1005.
AssociationforComputationalLinguistics(2010)17.
Potthast,M.
,Stein,B.
,Eiselt,A.
,Barrón-Cedeo,A.
,Rosso,P.
:Overviewofthe1stInternationalCompetitiononPlagiarismDetection.
In:Stein,B.
,Rosso,P.
,Stamatatos,E.
,Koppel,M.
,Agirre,E.
(eds.
)SEPLN09WorkshoponUncoveringPlagiarism,Authorship,andSocialSoftwareMisuse(PAN09).
pp.
1–9.
CEUR-WS.
org(Sep2009),http://ceur-ws.
org/Vol-50218.
Stein,B.
,zuEissen,S.
M.
,Potthast,M.
:Strategiesforretrievingplagiarizeddocuments.
In:Proceedingsofthe30thannualinternationalACMSIGIRconferenceonResearchanddevelopmentininformationretrieval.
pp.
825–826.
ACM(2007)19.
Stein,B.
,Rosso,P.
,Stamatatos,E.
,Koppel,M.
,Agirre,E.
:3rdpanworkshoponuncoveringplagiarism,authorshipandsocialsoftwaremisuse.
In:25thAnnualConferenceoftheSpanishSocietyforNaturalLanguageProcessing(SEPLN).
pp.
1–77(2009)
美得云(20元)香港特价将军澳CTG+CN2云服务器
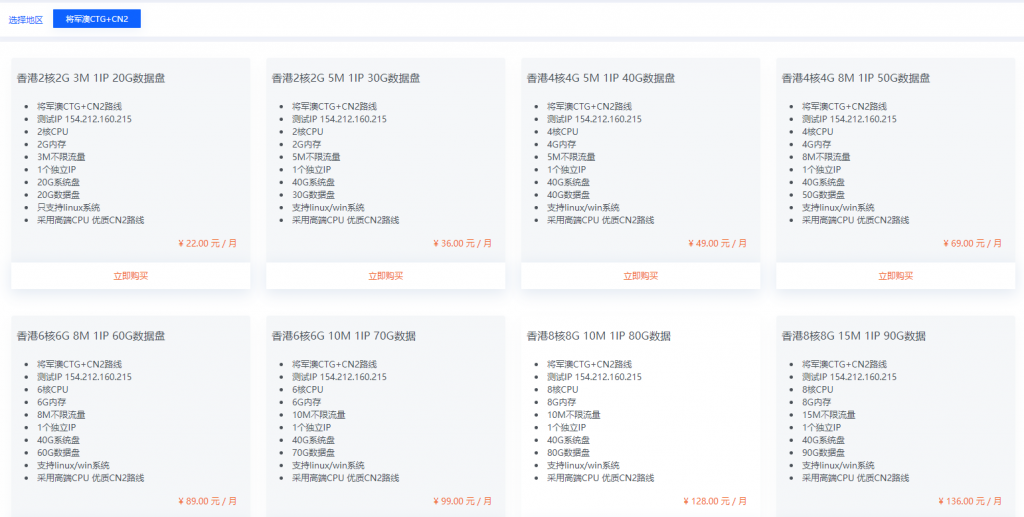
美得云成立于2021年,是一家云产品管理服务商(cloud)专业提供云计算服务、DDOS防护、网络安全服务、国内海外数据中心托管租用等业务、20000+用户的选择,43800+小时稳定运行香港特价将军澳CTG+CN2云服务器、采用高端CPU 优质CN2路线 SDD硬盘。香港CTG+CN22核2G3M20G数据盘25元点击购买香港CTG+CN22核2G5M30G数据盘39元点击购买香港CTG+CN...
华为云(69元)828促销活动 2G1M云服务器
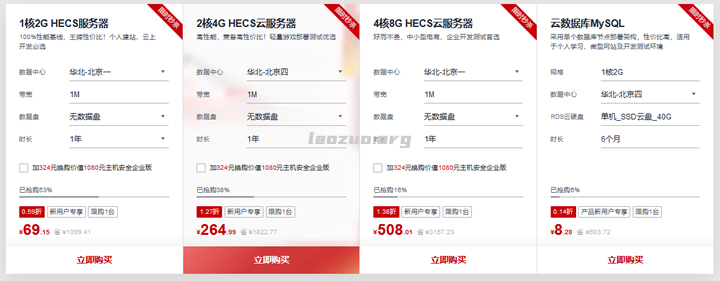
华为云818上云活动活动截止到8月31日。1、秒杀限时区优惠仅限一单!云服务器秒杀价低至0.59折,每日9点开抢秒杀抢购活动仅限早上9点开始,有限量库存的。2G1M云服务器低至首年69元。2、新用户折扣区优惠仅限一单!购云服务器享3折起加购主机安全及数据库。企业和个人的优惠力度和方案是不同的。比如还有.CN域名首年8元。华为云服务器CPU资源正常没有扣量。3、抽奖活动在8.4-8.31日期间注册并...
incogne$2.5/月t芬兰VPS,AMD Ryzen、1Gbps带宽
IncogNet LLC是个由3个人运作的美国公司,主要特色是隐私保护,号称绝对保护用户的隐私安全。业务涵盖虚拟主机、VPS等,支持多种数字加密货币、PayPal付款。注册账号也很简单,输入一个姓名、一个邮箱、国家随便选,填写一个邮箱就搞定了,基本上不管资料的真假。当前促销的vps位于芬兰机房,全部都是AMD Ryzen系列的CPU,性能不会差的!5折优惠码:CRYPTOMONTH,支持:BTC,...
雅虎社区为你推荐
-
缓冲区溢出教程溢出攻击法使用什么样的原理吴晓波频道买粉罗辑思维,晓松奇谈,鸿观,吴晓波频道,财经郎眼哪个更有深度pwlosera,pw是什么,是不认识的人发的短信。请解释::1433端口怎么开启本机1433端口照片转手绘美图秀秀可以照片转手绘吗?是手机版的显卡温度多少正常显卡温度多少正常天天酷跑刷金币天天酷跑如何刷分刷金币?人人逛街包公免费逛街打一成语bt封杀现在是全面封杀BT下载了吗?现在都找不到BT下载影片了什么是云平台什么是云系统?