belongingpagerank
pagerank 时间:2021-04-19 阅读:()
NewversionsofPageRankemployingalternativeWebdocumentmodels1MikeThelwallSchoolofComputingandInformationTechnology,UniversityofWolverhampton,35/49LichfieldStreet,WolverhamptonWV11EQ,UKm.
thelwall@wlv.
ac.
ukLiwenVaughanFacultyofInformationandMediaStudies,UniversityofWesternOntario,London,Ontario,N6A5B7,Canadalvaughan@uwo.
caKeywords:WebIR,PageRank,hyperlinkanalysis,searchenginesAbstractWeintroduceseveralnewversionsofPageRank(thelinkbasedWebpagerankingalgorithm),baseduponaninformationscienceperspectiveontheconceptoftheWebdocument.
AlthoughtheWebpageisthetypicalindivisibleunitofinformationinsearchengineresultsandmostWebinformationretrievalalgorithms,otherresearchhassuggestedthataggregatingpagesbasedupondirectoriesanddomainsgivespromisingalternatives,particularlywhenWeblinksaretheobjectofstudy.
ThenewalgorithmsintroducedbaseduponthesealternativeswereusedtorankfoursetsofWebpages.
Therankingresultswerecomparedwithhumansubjects'rankings.
Theresultsofthetestsweresomewhatinconclusive:thenewapproachworkedwellforthesetthatincludespagesfromdifferentWebsites;however,itdoesnotworkwellinrankingpagesthatarefromthesamesite.
Itseemsthatthenewalgorithmsmaybeeffectiveforsometasksbutnotforothers,especiallywhenonlylownumbersoflinksareinvolvedorthepagestoberankedarefromthesamesiteordirectory.
IntroductionCommercialsearchenginesareakeyaccesspointtotheWebandhavethedifficulttaskoftryingtofindthemostusefulofthebillionsofWebpagesforeach–typicallyshort(Spinketal.
,2001)–userqueryentered.
Probablythetaskismostdifficultwhenmillionsofpagescontainthequeryterm(s)andthesemustbeorderedsothattheuserispresentedwiththemostlikelyones.
Google'sPageRank(BrinandPage,1998)wasanattempttoresolvethisdilemmabasedupontheassumptionsthat:(1)moreusefulpageswillhavemorelinkstothemand(2)linksfromwelllinkedtopagesarebetterindicatorsofquality.
ThecontinuedriseofGoogletoitscurrentdominantposition(Sullivan,2002)andtheproliferationofotherlinkbasedalgorithms(e.
g.
Kleinberg,1999;CrestaniandLee,2000;Ngetal.
,2001;AltaVista,1Thelwall,M.
&Vaughan,L(2004).
NewversionsofPageRankemployingalternativeWebdocumentmodels.
ASLIBProceedings,56(1),24-33.
12002)seemstomakeanunassailableargumentforthePageRankalgorithm,despitethepaucityofclearcutresults(e.
g.
Hawkingetal.
,2000;SavoyandPicard,2001).
ModernWebIRalgorithmsareprobablyahighlycomplexmixtureofdifferentapproaches,perhapsoptimisedusingprobabilistictechniquestoidentifythebestcombination(e.
g.
Gaoetal.
,2001;XiandFox,2001;TsikrikaandLalmas,2002;SavoyandPicard,2001).
Itisnotpossibletobedefinitiveaboutcommercialsearchenginealgorithms,however,sincetheyarekeptsecretapartfromthebroadestdetails.
InfactacademicresearchintoWebIRisinastrangesituationsinceresearchbudgetsanddatasetscouldbeexpectedtobedwarfedbythoseofthecommercialgiants,whoseexistencedependsuponhighqualityresultsinanincrediblycompetitivemarketplace.
OnepaperthatcomparedthetwofoundthattheacademicsystemswereslightlybetterbuttheauthorsadmittedthatthetaskswereuntypicalforWebusers(Hawkingetal.
,2001a).
Nevertheless,Googleisonecaseamongstmanyofsearchalgorithmsgainingfromapproachesanddevelopmentsininformationscienceingeneralandbibliometricsinparticular.
Thealternativedocumentmodels(Thelwall,2002a)areanexampleofatheoreticalapproachfrominformationsciencethatmaybringbenefitstoWebIR.
TheprinciplebehindthesemodelsisthatWebpagesoftennaturallyclusterintorecognisabledocumentsbaseduponthedirectoryordomainthattheyarein.
Whenworkingwithlinksitcanoftenmakesensetoutiliseadirectoryordomainlevelofaggregation,especiallyifeachindividualpagecontainsasetofidenticallinks,perhapsinastandardnavigationbar.
Theresultofaggregationinsuchacasewouldbetheremovalofallduplicatelinks,givingamoreappropriatelinkcount.
Thisapproachhasbeenshowntogiveimprovedacademiclinkmetrics(Thelwall,2002a;ThelwallandTang,2003;ThelwallandWilkinson,2003;ThelwallandHarries,2003).
Furthersupportforthesemodelsisgivenbytheirabilitytocluster(setsof)Webpagesindifferentandnon-trivialways(Thelwall,2003).
Anaturalquestion,therefore,iswhetherWebIRalgorithmscanbenefitfromthealternativedocumentmodels.
Inthispaper,newversionsofPageRankwillbeintroducedusingalternativedocumentmodels.
TheeffectivenessofthesenewrankingalgorithmswillbecomparedagainstthatofthestandardPageRank.
Humanrankingjudgementwillbeusedasthebenchmarkagainstwhichtocomparedifferentalgorithms.
VersionsofPageRankbasedonthealternativedocumentmodelPageRankwasdevelopedbythefoundersofGoogle,SergeyBrinandLawrencePage(1998).
Thegeniusoftheapproachisthatthealgorithmissimpleandintuitive,yetadmitsamathematicalimplementationthatscalestothebillionsofpagescurrentlyontheWeb.
Forourpurposes,sincewearenotmodifyingthemathematicalalgorithmofPageRankbutonlythedocumentspaceuponwhichitisapplied,wewilldescribetheprincipleofPageRankbutnotthedetailsofitsimplementation.
TheprecisedetailsofthemathsandfurtherdescriptionscanbefoundintheoriginalPageRankpaper(BrinandPage,1998)aswellasseveralotherrelatedpapers(Haveliwala,1999;Lifantsev,2000;Ngetal.
,2001;Thelwall,2002b).
EssentiallytheapproachusedbyPageRankcanbedescribedwithavotingmetaphor.
Atthestartoftheprocess,eachWebpageisallocatedavotep.
Forexample,eachpagemaybeallocatedthesamevalue0.
1.
EachpagethensharesafractionofαPageRankwereused.
Incontrast,apurelytext-matchingalgorithmwouldhavegreatdifficultyindecidingwhichpagecontainingthematchingtextwasthemostrelevant.
AcriticismoftheoriginalPageRankisthatmanypagesreceiveahighnumberoflinksforreasonsotherthantheirquality.
Forexample,somesiteshaveastandardnavigationbaroneachpage,allcontainingalinktothehomepageandafewotherpages.
Forthesiteitself,thisprobablydoesservetoindicatethemostusefulpages,butrelativetoothersitesthetotalnumberofpagescontainingthelinkbarwillbecriticaltodeterminethefinalPageRankofthetargetedpages,meaningthatlargersiteswillautomaticallyrankhigher.
Ithasalsobeennotedthatlinksbetweenpageswithinasitearetypicallyfornavigationpurposes,andthereforearelessreliableasindicatorsoftargetpagequalitythanlinksbetweensites.
Moreover,navigationbarssometimescontainlinkstoothersitesandonesiteoftencontainsmultiplelinkstoanotherforreasonsthatarenotrelatedtotargetsitequality.
AllofthesefactorsunderminetheeffectivenessofPageRankasanindicatorofthequalityofthepage.
Anadditionalproblemistheorganisationofinformationbysite,domainordirectory.
Forexample,asitecontainingmuchhighqualityinformationmayreceivemanylinkstoitshomepage,whereasitsactualcontentisontensofthousandsofotherpagesunderthehomepage,mostofwhichdonotreceivemanylinks.
AcaseinpointforthisistheMicrosoftsitethatincludesanenormousbodyofauthoritativeinformationspreadovermanypages.
Intheory,linkstothehomepagewillredistributethroughthelayersofasitetothesecontentcarryingpages,butinpracticethisdoesnotwork(Thelwall,2002b)andsothecontentpageswillnotreflecttheprestigeofthehostingsite.
Thisisanargumentforincludinginrankingmeasuresanassessmentofthesiteasawholeinadditiontotheindividualpages.
AsimilarargumentcanbemadeforanycoherentclusterofWebpageswitharecognisablehomepage.
Basedupontheargumentsmadeabove,theclaimisthatPageRankcanbeimprovedbyincorporatingrankingsofapagebaseduponitshostingsite,domainanddirectory.
Aprecisedefinitionofdocumentmodelsbasedupontheselevelsofaggregationisgivenbelow(takenfromThelwall,2002a).
IndividualWebpage.
EachseparateHTMLfileistreatedasadocumentforthepurposesofextractinglinks.
EachuniqueURLinalinkistreatedaspointingtoaseparatedocumentforthepurposesoffindinglinktargets.
URLsaretruncatedbeforeanyinternaltargetmarker'#'characterisfound,however,toavoidmultiplereferencestodifferentpartsofthesamepage.
3Directory.
AllHTMLfilesinthesamedirectoryaretreatedasasingledocument.
AlltargetURLsareautomaticallyshortenedtothepositionofthelastslash,andlinksfromdifferentpagesinthesamedirectoryarecombinedandduplicateseliminated.
Domainname.
AsaboveexceptallHTMLfileswiththesamedomainnamearetreatedasasingledocumentforbothlinksourcesandlinktargets.
Inparticular,thisclusterstogetherallpageshostedbyasinglesubdomainofauniversitysite.
University.
Asaboveexceptthatallpagesbelongingtoauniversityaretreatedasasingledocumentforbothlinksourcesandlinktargets.
ApplyingPageRanktothesemodelsmeansallocatingvotesattheappropriatedocumentlevelanddistributingthemaccordingtolinksidentifiedasabove.
Forexample,inthecaseofthedomain-basedPageRank,itwouldstartwithavotepbeingallocatedtoeachdirectoryandthenafractionαofitbeingredistributedequallytoalldirectoriesthatarelinkedtobythisdirectory.
Theextrabonusvote(1-α)pwouldalsobeallocatedtoeachdirectory.
Subsequentvotingroundswouldthenfollowthesameprinciple.
StandardPageRankisbasedonthepagelevelmodeldescribedabove.
Weintroducethreenewalgorithms:PageRankusingthedirectory,domainanduniversitydocumentmodelswiththeadditionalmodificationthatonlylinksbetweendifferentsites(inourcaseuniversities)willbeused.
Thisisbaseduponthehypothesisthatlinksinsideasiteareprimarilyfornavigationpurposes,whereaslinkstoexternalsitesaremorereliableasindicatorsoftargetquality.
ThevariantswillbecalledintersitedirectoryPageRank,intersitedomainPageRankandintersiteuniversityPageRank.
ItwouldalsobepossibletoapplyPageRanktothepagemodelafterexcludinginternalsitelinks,butthiswouldnotbeeffectivesincerelativelyfewpagesaretargetedbyothersitesandsoalmostallpageswouldberankedlast.
LiteratureReviewWebIRalgorithmsAlthoughthemaintaskoftheearlysearchenginessuchastheWorldWideWebWorm(Chun,1999)wastofindWebpages,therapidgrowthoftheWebmeantthattechnicaldevelopmentquicklyswitchedtofindingthemostrelevantpagesforuserqueries.
Thisleadtoincreasinglyrefinedtextmatchingtechniques,suchaslatentsemanticindexing(Deerwesteretal.
,1990)wherethequerytermsdonothavetobeinthepageforittoberetrieved,butwithlinkbasedalgorithms,suchasGoogle'sandKleinberg's,therelationshipbetweenpagesandthosesurroundinghasbecomeimportant.
ThesuccessoflinkapproacheshasnotbeenreplicatedinthecomputerscienceTRECtasks,however,perhapsduetoanuntypicaltestcorpusused,oruntypicaltasks(Hawkingetal.
,2000).
Anothertrendisfortheapplicationofmultipletechniquesinablendtoobtainoptimalresults.
Forexample,textmatchingcanbecombinedwithlinkalgorithmsandURLstructureheuristicsinordertoidentifyhomepages,animportanttask,asreflectedinitsinclusionintheTRECWebtrack.
Variousmethodsareavailabletoidentifythebestweightingstousetocombinethesealternativetechniques(e.
g.
Gaoetal.
,2001).
Oneside-effectofthis,however,isthattheconstructionofanefficientpieceofsoftwarewillnotleadtoclearresultsabouttheusefulnessofanyoneofthecomponentsofitsalgorithm.
Conversely,evaluatingoneapproachonitsown,whilstyieldingsuchresults,willnotyieldanoptimalsystem.
Oneimplicationofthisisthat4researchintoindividualcomponentscanincreasinglybeseenasinformationscienceratherthancomputerscience.
OthervariationsofPageRankSeveralvariationsorgeneralisationsofPageRankhavebeensuggested.
Infactitsoriginatorssuggestedafewmodificationsattheoutset,includingusinganon-uniformpatternofinitialvotessothatPageRankcouldbepersonalisedtotheuser,bygivingtheirvaluedpageshigherinitialpvalues(BrinandPage,1998).
ThisapproachcanalsobeusedtoalterthePageRankresultsthroughtheinclusionofanothersourceofinformationaboutpagequality.
BharatandMihaila(2001)developedanewversionofPageRankanddemonstratethroughuserevaluationsthatitsperformanceiscomparablewiththestandardPageRank.
Lifantsev(2000)developedageneraltheoreticalmodelforapplyingvariantsofthePageRanktechnique.
Haveliwala(1999)developedcomputingtechniquestoapplystandardPageRanktosmallerplatforms.
Meghabghab(2002)proposedaversionbaseduponinandoutdegreesofnodes,butthisdidnotproduceimprovedresults.
RichardsonandDomingos(2001)developedacombinationofPageRankwithcontentinformation,andprobablythisiswhatGoogledoesalready.
SearchenginequalityevaluationtechniquesAlthoughmanymeasureshavebeenusedtoassesstheretrievalresultsofasearchengine(e.
g.
Hawkingetal.
,2001a)theconcerninthisstudyisonlywithevaluatingasearchengine'sabilitytorankthepagesretrievedonaparticulartopic.
Asaresult,thenormalquestionsofprecision(thepercentageofpagesreturnedthatarerelevanttothetopic)andrecall(thepercentageofrelevantpagesfoundontheWeb)donotapply,sincethesearetypicallybaseduponbinarydecisionsofrelevanceandnotonrelativemeritsofthepagesthemselves.
Forexample,TRECtypeevaluationsfocusonwhethereachpagedoesmatchthecriteriaofthesearchratherthanonthequalityofthepagecontent.
Evaluationofrankingperformancehasactuallybeenaparticularlytroublesomeandcontroversialaspectofsearchengineresearch.
Manypapersdescribingadvanceshavegivenanecdotalratherthanformalevaluations(BrinandPage,1998).
TherelevanceofthedocumentsinTRECtopicsareformallyevaluatedinbatchesbyagroupofhumans(Hawkingetal.
,1999)butthisapproachhasbeencriticisedonthegroundsthatonlyarealenduserofinformationcansuccessfullyevaluateretrievalresults(GordonandPathak,1999).
Anotherapproach,unavailabletomostresearchers,istoanalysesearchenginelogfilestominesearchpatterns(e.
g.
Spinketal.
,2001).
Commercialsearchenginesprobablyemployacombinationofevaluationmethodsbutnoneareidealbecauseof(a)thediversityofinformationontheWeband(b)thedifficultyofgettingagroupofuserstoevaluateasimilarsetofresultsinawaythatisnotartificial.
Asaresult,anyevaluationprocesswillnecessarilybeacompromisebutthetaskoftheresearcheristoovercometheseobstaclesaseffectivelyaspossible.
ResearchquestionsThequestionsaddressedarewhetheranyofthefollowingalternativeversionsofPageRankproducesimprovedrankingsoverstandardPageRank.
PageRankwithinternalsitelinksexcludedandbasedupon:5thedomain,thedirectory,ortheuniversitydocumentmodel.
FoursetsofWebpagesonfourdifferenttopicswereselectedforthestudy(detailsofthechoiceofpagesarebelow).
Eachsetofpageswasrankedbyhumansubjects(detailsbelow).
DifferentversionsofPageRankalgorithmwereusedtorankeachsetofpagesandtherankingresultscomparedwiththatofhumansubjects.
Thealgorithmthatgeneratesarankingclosertothehumanrankingisconsideredtobebetter.
DataCollectionSubjectsofthestudySubjectsofthestudywerestudentsenrolledontheInformationRetrievalcourse,partoftheMasterofLibraryandInformationSciencedegree,inthesummertermof2002attheFacultyofInformationandMediaStudies,UniversityofWesternOntario,Canada.
OneoftheassignmentsofthecoursewastorankasetofWebpagesandthencomparetherankingagainstthosegeneratedbydifferentsearchalgorithmstogainanunderstandingofsearchalgorithmsandsearchengines.
Twenty-fourstudentsonthecourseweredividedrandomlyintofourgroupsofsixpeopleeach.
EachgroupwasgivenasetofWebpagesonaparticulartopic(detailsbelow)andeachstudentindependentlyrankedthepagesinthewaythathe/shethoughttheyshouldberankedinasearchoutput.
Thegroupthenmetandexchangedtheirrankingaswellasthecriteriausedintheranking.
Eachstudentthendidanotherroundoftherankingbasedonthediscussionwithothergroupmembers(theycouldchoosenottochangetheirrankingfromthefirstroundofexercise).
Studentsthenproceededwiththeotherpartsoftheassignmentthatwerenotdirectlyrelatedtothestudy.
Forthepurposeofthisstudy,studentrankingresultswereaggregated(detailsindataanalysisbelow)andusedasthebenchmarkagainstwhichtocomparerankingresultsfromdifferentPageRankalgorithmsunderinvestigation.
Basedontheethicalprincipleofvoluntarilyparticipation,studentsweregiventhechoiceofallowingtheirrankingdatatobeusedforthestudyornot.
Allstudentsonthecoursegavepermissiontousetheirdataforthestudy.
ChoiceofpagesetsBecauseallsubjectsinthestudywereCanadiangraduatestudents,thetopicsofthepagestoberankedwereallchosentoberelatedtoCanadianuniversitylifesothatstudentswereknowledgeableaboutthesubjectandwerecompetenttorankthepages.
Thefollowingfourtopicswereselected:1.
OntarioGraduateScholarshipinScienceandTechnology(referredtoasOGSbelow).
2.
SocietyofGraduateStudiesattheUniversityofWesternOntario(referredtoasSOGSlater).
3.
OmbudspersonofficeattheUniversityofWesternOntario(ombudspersonforshort).
4.
AdmissionrequirementsfortheMBAprogramattheUniversityofToronto(MBAforshort).
6AsetofWebpagesoneachtopicwereretrievedusingthreesearchengines(Google,AltaVista,andTeoma)andthetop10pagesretrievedbyeachengineweremergedtoformthesetofpagesforthatparticulartopic.
Asaresult,therewereabout20pagesineachsettoberanked.
Whenperformingthesearchonthesearchengines,restrictionsbydomainswereimposedtoavoidtheinclusionoftotallyirrelevantpages.
Forexample,thesearchofpagesonSOGSwasrestrictedtothedomainofwww.
uwo.
ca(theuniversity'sURL)sothatirrelevantpagesthathappenedtohavethewordSOGSwerenotlikelytoberetrieved.
Therankingofthesepagesbythesearchengineswerenotrevealedtothesubjectsbeforetheydidtherankingtoavoidpossiblebias.
DataforcalculatingPageRankscoresAsexplainedabove,thecalculationofPageRankscoresarebasedonthelinkinginformationamongpages.
SearchenginessuchasGoogleuselinkstructuresamongallpagesintheirdatabasetocalculatethePageRankscores.
Forthepurposeofthisstudy,auniverseofpagesmustbedefinedonwhichtobasethecalculationofPageRankscores.
ItwasdecidedtouseallCanadianuniversityWebpagestobesuchauniversebecause:(1)itisimpossibletocoverallpagesontheWebforaproject;(2)allpagestoberankedareaboutCanadianuniversitiessothelinkstothesepagesaremostlikelytocomefromotherCanadianuniversities;(3)itisfeasibletocrawlthisnumberofpages(3,930,113intotal)andrecordtheirlinkinginformation.
Theunderlyingassumptionofthisdatacollectionmethodisthatsimilarresultswouldbeobtainedifafullsearchenginedatabaseweretobeused.
Althoughthisassumptionisimpossibletoverify,itissupportedbytherobustnessofthePageRankalgorithm(Ngetal.
,2001).
Inanycase,theperformanceofPageRankonanyconceptuallycoherentsetofpagesisofinterestandappropriate.
TheURLsofallCanadianuniversitieswereobtainedfromanonlinelist(AssociationofUniversitiesandCollegesofCanada,2002)andtheexhaustivityofthesetverifiedandsupplementedusinganunrelatedprintmediasource(Johnston,2002).
Thelistincludedallfulluniversitiesaswellasaffiliatedcolleges.
EachuniversityWebsitewasthencrawledbyaspecialistinformationscienceWebcrawler(Thelwall,2001a)torecordlinkinformation.
Thecrawlerwasdesignedtocoversitesaccurately,checkingforduplicatepagesexhaustively.
Thecrawlercannormallyonlyfindpagesbyfollowinglinksiterativelyfromthehomepageandsopagesthatwerenotlinkedtowouldnothavebeencovered.
Twoexceptionsweremade,however.
Firstly,someuniversities'homepagesdidnotcontainanyHTMLlinksandsoastandardcrawlwouldreturnonlyonepage.
Inthesecasesapageoflinkstoalldepartmentalhomepageswassoughtandusedasanalternativestartingpoint.
Secondly,theURLsofthefoursetsofpagesusedinthestudywerepreloadedintothecrawlertoensurethattheywouldbecovered,evenifnolinkstothemhadbeenfound.
Someareaswereexcludedonthebasisofbeingmirrorsitesorhugeonlinedatabaseswithonlyinternallinks.
Thecrawlingwasconductedinthesummerof2002,shortlybeforethepagesfortheexperimentwererankedbythestudents.
DataAnalysis7Asdiscussedin'Datacollection',eachsubjectrankedthesetofpagestwice.
Thesecondroundofranking,afterthegroupdiscussion,representsthefinalrankingdecisionandwasthususedfordataanalysis.
Only9outof24subjectschangedtheirrankingfromthefirstroundandmostchangesareminorinvolvingonlyafewpages.
Theaverageofthesixgroupmembers'rankingwastakentorepresenthumanrankingforthatsetofpages.
Althoughindividualstudent'srankingsdiffered,theyweremostlycorrelatedwitheachother,whichprovidessomeassuranceofthereliabilityofthehumanrankingdata.
TherankinggeneratedbyeachPageRankalgorithmwascorrelatedwiththehumanrankingtoseewhichalgorithmwasbetter(i.
e.
closertohumanranking).
TheSpearmancorrelationcoefficienttestwasusedbecausethehumanrankingscoresareobviouslyordinaldata.
ResultsTheresultsofcorrelationtestsaresummarizedinTableI.
Thefoursetsofpagesarelabelledwiththeiracronyms(see'Choiceofpagesets'aboveforadetaileddescriptionofthecontentofeachset).
ThefirstcolumnofdatainTableIgivesthecorrelationcoefficientsbetweenhumanrankingandtherankingbythestandardPageRank.
TheothercolumnsshowthecorrelationbetweenhumanrankingandtherankinggeneratedbyvariousversionsofPageRankemployingalternativedocumentmodels.
Thecolumnlabelled'directory'representsthePageRankusingthedirectoryleveldocumentmodel.
Thecolumnslabelled'domain'and'university'areforPageRanksusingdomainlevelanduniversityleveldocumentmodelsrespectively.
TableICorrelationsbetweenhumanrankingandrankingbyalgorithmsPageSetStandardPageRankIntersitedirectoryPageRankIntersitedomainPageRankIntersiteuniversityPageRankOGS-0.
08-0.
060.
320.
05Ombudsperson0.
600.
63N/AN/AMBA0.
2-0.
14-0.
29N/ASOGS0.
27N/AN/AN/ATheN/AsigninTableImeansthatPageRankscoresarethesameoralmostthesameforallpagesinthesetandthuscorrelationcoefficientcannotbecalculated.
ItshouldbenotedthatthepresenceofsomanyN/AsignsinTableIshouldnotbeinterpretedtomeanthatthealternativedocumentmodelswouldfrequentlynotprovideusefulPageRankdata.
Itistheresultofthewaythatthepageswereselected.
Recallthatrestrictiontoaspecificdomainwasnecessarywhenformingthepageset.
Forexample,theSOGSpagesetwasretrievedexclusivelyfromthedomainofwww.
uwo.
ca.
InfacttheuniquewordSOGScausedtheretrievedpagestoallcomefromthesamedirectorywww.
uwo.
ca/sogs/.
ThisexplainswhyPageRankbasedonthedirectory,domain,anduniversitylevelcannotprovidedatathatdistinguishespageswithinthisset.
Forthisreason,thissethadtobeomittedfromthetestsofalternativedocumentmodels.
CorrelationcoefficientsthatarestatisticallysignificantareshowninboldfaceinTableI.
ThestandardPageRankhadasignificantcorrelationforonlyoneoutofthefoursetsofpagesusedinthestudy,theombudspersonset.
PageRankbasedonthe8directoryleveldocumentmodelshowedaslightimprovementoverthestandardmodel.
TheonlypagesetthatisappropriatetotestthealternativedocumentmodelistheOGSsetbecausenorestrictiontoaparticularuniversity'sdomainwasimposedwhenformingthisset(OntarioGraduateScholarshipisnotrestrictedtoaparticularuniversity).
Asaresult,pageswithinthissetcomefromdifferentuniversitiesandthealternativedocumentmodelswereabletodistinguishthesepageswell.
Forthisset,thestandardPageRankalmostrankedthepagesinthedirectionoppositetothatbyhumansubjects(themeaningofthenegativecorrelation).
PageRankbasedonthedomainleveldocumentmodelshowsanadvantageoverthestandardmodelwhiletheuniversitylevelmodelshowedonlyaveryslightimprovement.
ResultsfromtheMBAsetcameasasurpriseinthatthealternativedocumentmodelsshoweddisadvantageoverthestandardPageRankmodel.
Itisnotclearwhetheritisananomalouscaseorwhetherthealternativedocumentmodelsarenotappropriateinsomecases.
OnepossibleexplanationforthefailureinthispagesetisthatthePageRankscorescalculatedforthissetarenotreliable.
RecallthatthePageRankscoresarecalculatedfromthedatabasethatincludesallCanadianuniversityWebpages.
TheMBApagesetiscentredaroundtheWebsiteoftheBusinessSchooloftheUniversityofToronto.
DuetothenatureoftheSchool,therearemanylinkstotheWebsitethatarenotfromotherCanadianuniversities.
Forexample,asearchoflinkstothissiteusingAltaVistasearchenginesfoundoveronehundredlinksfrom.
comdomain.
ThePageRankcalculationmissedalltheselinksandisthereforebiased.
Thisproblemdoesapply,ornottothisextent,toothersetsoftestpagesinthestudy.
Forexample,theWebsitethattheombudspersonsetiscentredaroundonlyhasonelinkfromthe.
comdomain.
Futurestudiescanavoidthisproblembyamorecarefulexaminationofpagespriortotherankingexperiment.
DiscussionThestandardPageRankdoesnotseemtobeveryeffectiveinrankingWebpagesinthestudyasshownbythefactthatitsrankingscorrelatesignificantlywithhumanrankingsforonlyoneoutoffoursetsofpagestested.
AlternativeapproachesareneededtoimprovetheeffectivenessofPageRank.
ThestudyproposedandtestednewversionsofPageRankbasedonalternativedocumentmodels.
Althoughtheresultsfromthestudydonotprovideclearevidencethatthealternativemodelsarebetter,itshowedthatthesemodelshavesomepromise.
Infact,theresultsfromtheOGSpageset,theonlysetthatisappropriatetotestallthealternativedocumentmodels,showedasubstantialadvantageoftheintersitedomainPageRankoverthestandardPageRank.
Onefacthasemergedclearlyfromthisresearch:thatitisdifficulttoassessthequalityofWebrankingalgorithms,especiallythoseinvolvinglinks,andespeciallyforresearchersthatdonothaveaccesstoacrawlofasizeablepercentageoftheWeb.
Afullscientificevaluationwouldinvolvehugehumanandcomputingresources:ideallyarandomselectionofquerieswithresultsrankedbyarepresentativesetofusersforwhomthequeriesrepresentedrealinformationrequests.
Inordertobeabletochoosequeriesatrandom,accesstoamajorsearchengineserverloganditsdatabaseforcalculatingtherankingscoreswouldbeneeded.
TheTRECapproach(trec.
nist.
gov,Hawkingetal.
,2001b)toresolvingasimilarproblemisasensibleone:tohaveacentrallyorganisedandratedcollectionofpagesthataresharedforalgorithmtestingpurposesbyparticipatingresearchers.
However,thisdoesnotyetsatisfyourneedbecausethosepagesareassignedabinaryrelevancescorebutnotrankedbydegreeofrelevance.
Forthereasonsdiscussedabove,therankingtask9wouldbelikelytobemorecomplexandinvolvemoreandmoredifficultassessmentsthanthecurrentlyemployedbinaryrelevancejudgements.
OurcompromisewastochooseasmallsetoffourqueriesthatwererelevanttoafixedgroupofendusersandbelongedtoacoherentsubsetoftheWebthatcouldbecrawledandassumedtobesufficientlylarge(3,930,113pages)forrankingthepagesetschosen.
ThiswouldnotbeaproblemifinformationneedslinkcreationandinformationdistributionwereknowntobehighlyuniformandpredictableontheWeb,i.
e.
ifthechoiceoftopicforeachsetwereknownnottoinfluencetheeffectivenessofarankingalgorithm,butwebelievethatthisisnotthecase.
Onalargescale,linkpatternsappeartobereasonablypredictableinsomecontexts(Thelwall,2001b,2002a)andoveralargenumberofpagesitseemsintuitivelyclearthatthosewith,say,threelinkstothemwouldbe,onaverage,slightlybetterqualitythanthosewithonlytwo.
Nevertheless,linksarestilltypicallycreatedbyindividualsinanunsystematicfashionandnotsubjecttoanykindofqualitycontrol.
Asaresultitisdifficulttoclaimthatthreelinkstoapageislikelytoconsistentlyindicatebettertargetpagequalitycontentthantwo.
Thisismoreevidentifitisacknowledgedthatfactorsotherthanqualitycaninfluencelinkcounts,includingtargetpageage.
Asaresult,anygivenlink-basedrankingalgorithmislikelytobeeffectiveforsometopicsbutineffectiveforothers.
Moreover,withthelownumbersoflinkslikelytobeinvolvedinpagesforsometopics,itseemslikelythateventhemosteffectivealgorithmwouldregularlyfailforasignificantproportionofsearchtopics.
Therefore,itisprobablynotsurprisingthattheproposednewalgorithminthisstudydoesnotworkwellforallthesearchtopicsintheexperiment.
Futureresearchinthisareashoulddesignawiderrangeofsearchqueriesandavoidproblemsencounteredinthisstudy.
Insummary,itseemsthatonlyresearchersworkingfor,orinconjunctionwith,amajorsearchenginewouldbecapableoffullyassessingnewWebrankingalgorithms,andotherswillremainforcedtoextrapolatefromtheteststhattheyareabletorun.
ThemostpromiseforacademicresearchersprobablylieswithcentralisedinitiativessuchasTREC,although,ascanbeseenabove,thechoiceoftopicscanimpactonalgorithmsindifferentways,dependingonthedetailsoftheirworkings.
ConclusionsAlthoughthestudydidnotsucceedinprovidingadefiniteanswertotheresearchquestionsexamined,itprovidedsomeevidencethatthealternativePageRankalgorithmsproposedcouldhavethepotentialtoimprovethestandardPageRankmodel.
ThestudysucceededintestingWebIRalgorithmsusinganempiricalstudyinvolvinghumansubjects,adirectionthatwasnotfollowedbymanypreviousstudies.
TheultimatevalueofanyWebIRalgorithmliesonitsabilitytoservehumanneedsandthusthebestwaytotestthemistoseeiftheymatchthoseneeds.
FutureresearchwithalternativedocumentmodelbasedrankingalgorithmsshouldkeepthehumanrankingapproachofthestudybutdesignarangeoftestqueriesthatallinvolvepagesfromdifferentWebsites.
AcknowledgementWegratefullythankallstudentswhoparticipatedinthestudybygivingpermissionforustousetheirrankingdata.
Thestudywouldhavebeenimpossiblewithouttheirsupport.
References10AltaVista(2002),AltaVistaadvancedsearchtutorial–linkpopularity,availableat:help.
altavista.
com/adv_search/ast_haw_popularity(accessed6September2002).
AssociationofUniversitiesandCollegesofCanada(2002),TheDirectoryofCanadianUniversities–UniversityWebsites,availableat:www.
aucc.
ca/english/dcu/universities/universitysites.
html(accessed24April2002).
Bharat,K.
andMihaila,G.
A.
(2001),"Whenexpertsagree:usingnon-affiliatedexpertstorankpopulartopics",inTenthInternationalWorldWideWebConference,availableat:www.
www10.
org/cdrom/papers/474/index.
htmlBrin,S.
andPage,L.
(1998),"Theanatomyofalargescalehypertextualwebsearchengine",ComputerNetworksandISDNSystems,Vol.
30No.
1-7,pp.
107-117,availableat:citeseer.
nj.
nec.
com/brin98anatomy.
htmlChun,T.
Y.
(1999),"WorldWideWebrobots:anoverview",Online&CD-ROMReview,Vol.
23No.
3,pp.
135-142.
Crestani,F.
andLee,P.
L.
(2000),"SearchingtheWebbyconstrainedspreadingactivation",InformationProcessingandManagement,Vol.
36No.
4,pp.
585-605.
Deerwester,S.
,Dumais,S.
T.
,Furnas,G.
W.
,Landauer,T.
K.
andHarshman,R.
(1990),"Indexingbylatentsemanticanalysis",JournaloftheAmericanSocietyforInformationScience,Vol.
41No.
6,pp.
391-407.
Gao,J.
,Walker,S.
,Robertson,S.
,Cao,G.
,He,H.
,Zhang,M.
andNie,J-Y(2001),"TREC-10WebTrackExperimentsatMSRA384-392",TREC2001,availableat:trec.
nist.
gov/pubs/trec10/t10_proceedings.
htmlGordon,M.
andPathak,P.
(1999),"FindinginformationontheWorldWideWeb:theretrievaleffectivenessofsearchengines",InformationProcessing&Management,Vol.
35,pp.
141-180.
Haveliwala,T.
(1999),"EfficientcomputationofPageRank",StanfordUniversityTechnicalReport,availableat:dbpubs.
stanford.
edu:8090/pub/1999-31Hawking,D.
,Bailey,P.
andCraswell,N.
(2000),"ACSysTREC-8experiments",inVoorhees,E.
andHarman,D.
(Eds),InformationTechnology:EighthTextRetrievalConference(TREC-8),NIST,Gaithersburg,MD,USA,pp.
307-315.
Hawking,D.
,Craswell,N.
,Bailey,P.
andGriffiths,K.
(2001a),"Measuringsearchenginequality",InformationRetrieval,Vol.
4No.
1,pp.
33-59.
Hawking,D.
,Craswell,N.
,Thistlewaite,P.
andHarman,D.
(1999),"ResultsandchallengesinWebsearchevaluation",8thInternationalWorldWideWebConference,availableat:www8.
org/w8-papers/2c-search-discover/results/results.
html.
Hawking,D.
,Craswell,N.
,Thistlewaite,P.
andHarman,D.
(2001b),"ResultsandchallengesinWebsearchevaluation",ComputerNetworks,Vol.
31No.
11-16,pp.
1321-1330,availableat:www8.
org/w8-papers/2c-search-discover/results/results.
htmlJohnston,A.
D.
(Ed.
)(2002),TheMaclean'sGuidetoCanadianUniversities2002,RogersPublishing,Toronto,Canada.
Kleinberg,J.
(1999),"Authoritativesourcesinahyperlinkedenvironment",JournaloftheACM,Vol.
46No.
5,pp.
604-632.
Lifantsev,M.
(2000),"VotingmodelforrankingWebpages",inGraham,P.
andMaheswaran,M.
(Eds),ProceedingsoftheInternationalConferenceonInternetComputing,CSREAPress,LasVegas,Nevada,USA,pp.
143-148.
11Meghabghab,G.
(2002),"Google'sWebpagerankingappliedtodifferenttopologicalWebgraphstructures",JournaloftheAmericanSocietyforInformationScienceandTechnology,Vol.
52No.
9,pp.
736-747.
Ng,A.
Y.
,Zheng,A.
X.
andJordan,M.
I.
(2001),"Stablealgorithmsforlinkanalysis",inCroft,W.
,Harper,D.
,Kraft,D.
&Zobel,J.
(Eds)Proceedingsofthe24thAnnualInternationalACMSIGIRConferenceonResearchandDevelopmentinInformationRetrieval(SIGIR2001),ACMPress,NewYork,pp.
258-266.
Richardson,M.
andDomingosP.
(2001),"Theintelligentsurfer:probabilisticcombinationoflinkandcontentinformationinPageRank",posteratNeuralInformationProcessingSystems:NaturalandSynthetic2001,availableat:www.
cs.
washington.
edu/homes/mattr/doc/NIPS2001/qd-pagerank.
pdfSavoy,J.
andPicard,J.
(2001),"RetrievaleffectivenessontheWeb",InformationProcessingandManagement,Vol.
37No.
4,pp.
543-569.
Spink,A.
Wolfram,D.
,Jansen,B.
J.
andSaracevic,T.
(2001),"SearchingtheWeb:thepublicandtheirqueries",JournaloftheAmericanSocietyforInformationScienceandTechnology,Vol.
52No3,pp.
226-234.
Sullivan,D.
(2002),"Googletopsin'searchhours'ratings",SearchEngineWatch,availableat:searchenginewatch.
com/sereport/02/05-ratings.
html(accessed6September2002).
Thelwall,M.
(2001a),"Awebcrawlerdesignfordatamining",JournalofInformationScience,Vol.
27No.
5,pp.
319-325.
Thelwall,M.
(2001b),"ExtractingmacroscopicinformationfromWeblinks",JournaloftheAmericanSocietyforInformationScienceandTechnology,Vol.
52No.
13,pp.
1157-1168.
Thelwall,M.
(2002a),"ConceptualizingdocumentationontheWeb:anevaluationofdifferentheuristic-basedmodelsforcountinglinksbetweenuniversityWebsites",JournaloftheAmericanSocietyforInformationScienceandTechnology,Vol.
53No.
12,pp.
995-1005.
Thelwall,M.
(2002b),"Subjectgatewaysitesandsearchengineranking",OnlineInformationReview,Vol.
26No.
2,pp.
101-107.
Thelwall,M.
(2003),AlayeredapproachforinvestigatingthetopologicalstructureofcommunitiesintheWeb,JournalofDocumentation,59(4),410-429.
Thelwall,M.
andHarries,G.
(2003),"TheconnectionbetweentheresearchofauniversityandcountsoflinkstoitsWebpages:aninvestigationbaseduponaclassificationoftherelationshipsofpagestotheresearchofthehostuniversity",JournaloftheAmericanSocietyforInformationScienceandTechnology,Vol.
54No.
7,pp.
594-602.
Thelwall,M.
andTang,R.
(2003),DisciplinaryandlinguisticconsiderationsforacademicWeblinking:anexploratoryhyperlinkmediatedstudywithMainlandChinaandTaiwan,Scientometrics,Vol.
58No.
1,pp.
153-179.
Thelwall,M.
andWilkinson,D.
(2003),"ThreetargetdocumentrangemetricsforuniversityWebsites",JournaloftheAmericanSocietyforInformationScienceandTechnology,Vol.
54No.
6,pp.
489-496.
Tsikrika,T.
andLalmas,M.
(2002),"CombiningWebdocumentrepresentationsinaBayesianInferenceNetworkmodelusinglinkandcontent-basedevidence",inProceedingsof24thEuropeanColloquiumonInformationRetrievalResearch,(ECIR2002),pp53-72,Glasgow,Scotland.
Xi,W.
andFox,E.
A.
(2001),"MachineLearningApproachforHomepageFindingTask",TREC2001,pp.
686-697,availableat:trec.
nist.
gov/pubs/trec10/t10_proceedings.
html.
12
- belongingpagerank相关文档
- personpagerank
- originatingpagerank
- matrixpagerank
- errorpagerank
- estimatepagerank
- pagepagerank
CloudCone,美国洛杉矶独立服务器特价优惠,美国洛杉矶MC机房,100Mbps带宽不限流量,可选G口,E3-1270 v2处理器32G内存1Gbps带宽,69美元/月
今天CloudCone发布了最新的消息,推送了几款特价独立服务器/杜甫产品,美国洛杉矶MC机房,分配100Mbps带宽不限流量,可以选择G口限制流量计划方案,存储分配的比较大,选择HDD硬盘的话2TB起,MC机房到大陆地区线路还不错,有需要美国特价独立服务器的朋友可以关注一下。CloudCone怎么样?CloudCone服务器好不好?CloudCone值不值得购买?CloudCone是一家成立于2...
cloudcone:特价便宜VPS补货通知贴,SAS或SSD低价有磁盘阵列,SAS或SSD raid10 硬盘
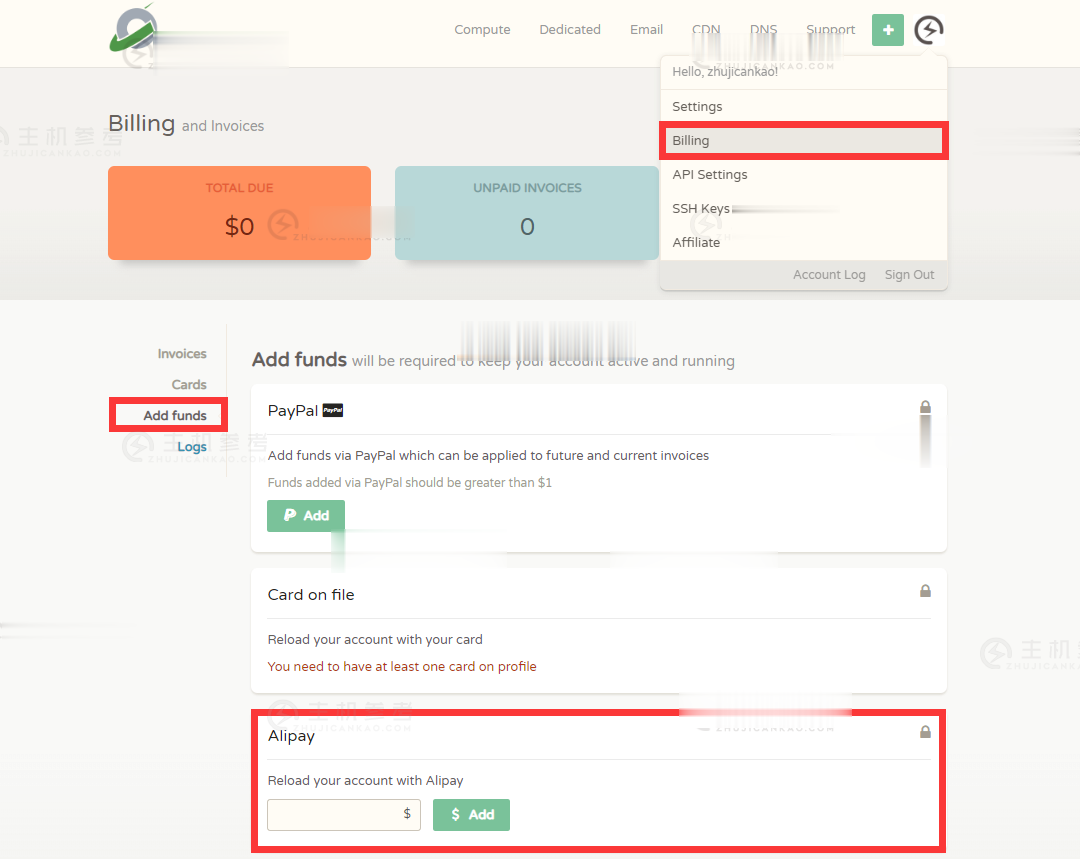
cloudcone经常性有特价促销VPS放出来,每次的数量都是相当有限的,为了方便、及时帮助大家,主机测评这里就做这个cloudcone特价VPS补货专题吧,以后每次放货我会在这里更新一下日期,方便大家秒杀!官方网站:https://cloudcone.com/预交费模式,需要充值之后方可使用,系统自动扣费!信用卡、PayPal、支付宝,均可付款购买!为什么说cloudcone值得买?cloudc...
Atcloud:全场8折优惠,美国/加拿大/英国/法国/德国/新加坡vps,500g大硬盘/2T流量/480G高防vps,$4/月
atcloud怎么样?atcloud刚刚发布了最新的8折优惠码,该商家主要提供常规cloud(VPS)和storage(大硬盘存储)系列VPS,其数据中心分布在美国(俄勒冈、弗吉尼亚)、加拿大、英国、法国、德国、新加坡,所有VPS默认提供480Gbps的超高DDoS防御。Atcloud高防VPS。atcloud.net,2020年成立,主要提供基于KVM虚拟架构的VPS、只能DNS解析、域名、SS...
pagerank为你推荐
-
linux防火墙设置如何使用iptables命令为Linux系统配置防火墙重庆电信断网电信光纤一直掉线,打电话问说是机房出了问题 要排查,已经一个星期了还没弄好,大概需要多久才能弄好?flashfxp下载我想下载一个FlashFXP 4.0.0 Build 1510 简体中文版的软件,可是不知道下载地址,希望大家帮帮我?课程cuteftpyixingjia通配符的使用方法大飞资讯新闻资讯包括什么内容?爱买网超艾比安高达厉害吗,今天在网上看到的万代的果断入手了,168贵吗,不知道这款高达厉不厉害青岛网通测速网通,联通,长城这三个宽带哪个网速最快?我是青岛的即时通EC营销即时通是什么?做什么的?oa办公软件价格一套OA办公系统多少钱