leadcentos6.0
centos6.0 时间:2021-03-27 阅读:()
TheNewAlgorithmoftheItem-basedonMapReduceZHAOWei1,a1CollegesoftwareTechnologySchool,ZhengzhouUniversityZhengzhou450002,Chinaaiezhaowei@163.
comKeywords:RecommendationsystemparallelcomputingClusteringAbstract.
TraditionalcollaborativefilteringalgorithmbasedonitemandK-meansclusteringalgorithmarestudied,theparallelalgorithmofcollaborativefilteringItem-basedonMapReduceisproposedbyusingMapReduceprogrammingmodel.
Thealgorithmismainlydividedintotwosteps,onestepisK-Meansalgorithmclusteringforusers,anotherstepistheparallelItem-basedalgorithmforclusteringuserrecommendation.
Experimentalresultsshowthatthealgorithmhasobtainedverygoodeffect,improvedtherunningspeedandexecutionefficiency,theimprovedalgorithmismuchsuitableforprocessingbigdata.
IntroductionBigdatausuallyincludesdatasetswithsizesbeyondtheabilityofcommonlyusedsoftwaretoolstocapture,curate,manage,andprocessdatawithinatolerableelapsedtime.
Bigdataishighvolume,highvelocity,and/orhighvarietyinformationassetsthatrequirenewformsofprocessingtoenableenhanceddecisionmaking,insightdiscoveryandprocessoptimization.
Volumemeansbigdatadoesn'tsample;itjustobservesandtrackswhathappens;Velocitymeansbigdataisoftenavailableinreal-time;Varietymeansbigdatadrawsfromtext,images,audio,video;plusitcompletesmissingpiecesthroughdatafusion[1].
Therefore,thebigdatamustbethroughthecomputerstatistics,comparison,analysisofthedatacanbetheobjectiveresults.
Nowelectroniccommercesystemsofeverytransaction,everyinputandeverysearchcanasdata,datathroughthecomputersystemtodothescreening,sorting,analysis,sothattheanalysisresultsisnotonlyanobjectiveconclusion,moreabletohelpbusinessprovidedthedecision-makingofenterprisesandalsocollectedusefuldatacanalsobereasonableplanning,activelyguidethedevelopmentoflargerpowerconsumption,andmoreeffectivemarketingandpromotion.
Withtheincreasingamountofdataintheelectroniccommercesystem,theneedforalargenumberofdatadepthanalysisisincreasinglyurgent.
Therefore,theuseofasimpleandhighscalabilityoftheprogramfortheanalysisofproductrecommendationisparticularlyimportant.
Atpresentdomesticmanyecommercesitesusecollaborativefilteringalgorithm,suchasAmazon,Dangdang,collaborativefilteringalgorithmismainlydividedintobasedontheitemsofthecollaborativefilteringalgorithmanduserbasedcollaborativefilteringalgorithm.
Basedonitemsofcollaborativefilteringalgorithmistomeasurethesimilaritybetweenitemsaccordingtotheuser'spreferences,donotneedtoconsidertheitemspecificcontentfeatures,sothealgorithmismainlyusedine-commercerecommendationandmovierecommendationdomain,thealgorithmwhileinthefieldofelectroniccommercerecommendationhasbeenacertaindegreeofsuccess.
Butinmassivedataarerecommendedwhenthedataisrecommendedperformanceisnothighandthedatainformationlackofsharingandextendedtheleadtothehardwarerequirementscomparedhigherinherentshortcomingsmakeitdidnotreceiveapromotionandsupportofenterpriseelectroniccommerce[2].
SoifweuseMapReducetoachievedistributedparallelcomputing,itwillgreatlyimprovetheefficiencyandperformanceofthealgorithm,andpromotethefurtherdevelopmentofthealgorithm[3-4].
Basedontheitemsofthecollaborativefilteringalgorithmisaccordingtoitemsimilarityanduserhistoryaccessrecordrecommendedtotheusertogeneratealistofitems,buttherearesomesmallproblems,suchasdatasparsityproblemandwhenthemassofusersandthenumberofitems,theuserbehaviorandrecorddatawillgreatly,andthealgorithmforcomputingitemswithsimilarmatrixcostgreatly,algorithmefficiencyandperformancewillgreatlyreduce.
Aimingattheaboveproblems,theclusteringalgorithmhasalsobeenappliedtoacollaborativefilteringalgorithmbasedonitem,themassiveuserclusteringanalysis,soitcanavoidthequestioncarefully,foreachusertorecommendoperation.
Thefirstshoppinguserswithsimilarinterestsintoauserclass,withaclusterofuserrecommendedgoodsarethesame.
Thesecondistoreducethemassiveuserdimensionsbecomedozensofclusteringlimited,thetimecomplexityencounteredabottleneck,andtheparallelclusteringalgorithmusingMapReduceistheeffectivewaytosolvethebottleneck[5].
MapReduceisadistributedprogrammingmodelframeworkonHadoopplatform,intheconditionofnotfamiliarwiththeunderlyingdetailsofthedistributedimplementationoftheimplementationoftheprogram[6].
TheMapReduceasparallelcomputingprogrammingmodel,firstofalltousersofMapReducebasedparallelclusteringandaccordingtotheresultsofuserclustering,ineveryuserclassusingtheMapReduceparallelcollaborativefilteringrecommendation,eventuallygiveusersareasonablepersonalizedcommodityrecommendationlist.
Therunningtimeofdifferentnodesinthequantitativedataiscomparedwiththenewalgorithm.
Theresultsshowthatthedataprocessingperformanceoftheproposedalgorithmisgreatlyimproved.
TheprincipleofMapReduceprogrammingmodelMapReduceisinHadoopplatformbyusingparallelcomputingprogrammingmodel,thetechniqueisproposedbyGoogleforatypicaldistributedparallelprogrammingmodel,theuserintheMapReducemodeldevelopthemapandreducefunctions,canrealizetheparallelprocessing.
Mapwillberesponsiblefordatadispersion,Reduceisresponsiblefordataaggregation.
UsersonlyneedtoachieveMapandReducetwointerface,youcancompletethecalculationofTBleveldata.
BecauseoftheMapReducemodel,thedetailsoftheparallelandfault-tolerantprocessingareencapsulated,whichmakesprogrammingveryeasytoimplement.
MapReduceparallelcalculationisdividedintotwoparts,thefirststepisinitializingtheoriginalinputdatafileandthedatasetisdividedintoapluralityofacertainsizeofdatablock,facilitateparallelcomputing;thesecondstepistostartthemapandreducefunctionsalgorithmofparallelcomputing,finallyproducedthefinalresult.
Figure1ParallelflowchartofMapReduceKeytechnologyresearchandImplementation1.
ThebasicideaofthetraditionalcollaborativefilteringalgorithmbasedonItem-basedThetraditionalbasedonitemsofcollaborativefilteringalgorithmthebasicideaisdividedintothreeparts,thefirstpartistocomputethesimilaritybetweenitems,commonsimilaritycalculationmethodwithcosinesimilarity,Pearsoncorrelationcoefficient,Tanmotocoefficientcorrelationof.
ThispaperselectstheEuclideansimilarityalgorithm,asfollows:TheassumptionisthatthereisavectorXandavectorY:X=(1x,2x,3x),Y=(1y,2y,3y),UsingtheEuclideansimilarityalgorithmtocalculatethesimilaritybetweenXandYSvector(x,y)formulaisasfollows[7]:1(,)1(,)Sxydxy=+(1)Where(,)dxyisthedistancebetweenthevectorXandY,thecalculationformulaisasfollows:222231123(dxyxyyyxx2)Thesecondpartistocalculatetheuserratingsmatrixontheitemsofthegoodsaccordingtothesimilaritymatrix;thethirdpartistheitemsimilaritymatrixWandtheusersoftheitemscorematrixmultiplicationtoobtaintherecommendationresults.
TraditionalItem-Basedcollaborativefilteringrecommendationalgorithmbasedonitemisthestagethataffectstheperformanceofthealgorithm.
Ifthenumberofusersisn,thenumberofcommodityitemsism,thetimecomplexityoffindingalltheitemsinthenprojectisO(2m),thetotalsearchspaceisnusers,sothetimecomplexityofcomputingsimilarityisO(2nm).
Sowhencalculatingthesimilaritymatrixofitems,itisindependentofthesimilaritybetweenthecalculatedandtheotherpairofitemstoaproject,soitispossibletocalculatethesimilaritymatrix.
2.
AnewalgorithmofItem-basedbasedonMapReduceThenewalgorithmismainlydividedintotwosteps;thefirststepistheMapReduceimplementationofK-Meansalgorithmbasedonclusteringofusers.
ThesecondstepistoachievetheparallelrecommendationalgorithmofItem-basedonMapReduce,theproductofuserclusteringrecommendation.
2.
1ThenewalgorithmK-MeansbasedonMapReduceThebasicideaofthetraditionalK-meansclusteringalgorithm:fromMdataobjectsinarbitrarychoiceofKobjectsastheinitialclustercenters;fortherestoftheotherobjects,accordingtotheirdistanceandtheclustercenters,respectively,theyallocatedtoitsmostsimilarclustering;thencalculateeachreceivedanewclusteringalgorithmclusteringcenter;keeprepeatingtheprocessuntilnochangesinacore.
Inthek-meansalgorithmtocalculatethedistancebetweendataobjectsandclustercentersisthemosttime-consumingoperation.
ThedataobjectandKclustercenterdistancecomparisonatthesametime,datafromotherobjectscanalsobecomparedwiththeKdistanceofthecenterofcluster,sotheoperationcanbeparallelized[8]BasedonMapReduceparallelimplementationofK-meansalgorithmcanimprovethespeedoftheclusteringalgorithm,isdividedintothreesteps:thefirststep:themapfunction,foreverypointcalculationrecentlythecenterdistanceandthecorrespondingtothenearestclustercenter.
Thesecondstep:Combinefunction,justcompletedtheMapmachineonthemachinearecompletedwiththesamepointoftheclusterpointofsummation,reducetheamountofcommunicationandcomputationofReduceoperation.
ThisstepisthekeytotheuseofCombinefunctiononthemachineonthefirstofthesameclustermerge,reducedtotheReducefunctionofthetransferandtheamountofcomputation.
Thethirdstep:theReducefunction,theintermediatedataofeachclustercenterwillbeformedandthenewclustercentercanbeobtained.
Eachiterationisrepeatedonthethreestep.
Figure2ParallelFlowChartofK-meansAlgorithmbasedonMapReduce2.
2thecollaborativefilteringalgorithmbasedonMapReduceforparallelimplementationofItem-basedBasedonthesimilaritycalculationformulamentionedabove(1),thispaperpresentsacollaborativefilteringrecommendationalgorithmbasedonMapReduce.
Algorithm1ThecollaborativefilteringrecommendationalgorithmbasedonMapReduceINPUT:Userinformationfile,Iteminformationfile,IntendeduserOUTPUT:IntendeduserrecommendedlistTheprocessisasfollows:Step1:Transformingtheuservectorintoanitemvector;Step2:Parallelcalculationofthesimilaritybetweenitems;thecalculationofthesimilaritybetweenitemsaccordingtotheformula(2)tocalculate;Step3:Similaritymatrixofparallelcomputingobjects;Step4:Parallelcomputinguserratingmatrix;inthecalculationoftheuser'sscoringmatrix,iftheuserisnotontheitemstoomuch,thenthedefaultscoreis1;Step5:Theresultsobtainedbythemultiplicationofthesimilaritymatrixofparallelcomputingobjectsandtheuser'sscorematrixarerecommended.
Experimentalresultanalysis1.
experimentalenvironmentThesimulationexperimentusingVMware_Workstation_10.
0.
3,virtualizationsoftwaretovirtualHadoopcloudplatform.
EightvirtualmachinesareinstalledonthevirtualHadoopcloudplatform,andaHadoopclusterenvironmentisbuiltontheseeightvirtualmachines.
OneofthevirtualmachineasagoodJobTrackernodeNameNode,theothersevenvirtualmachinesdeployedTaskTrackerandDataNode.
Thesemachinesareinthesamelocalareanetwork.
Theexperimentuseseightsetsofvirtualmachinehardwareconfigurationandsoftwareconfigurationasshownintable1:Table1HadoopClusterConfigurationOSCentos6.
4JDKVersion1.
6.
0Hadoop1.
1.
2HardWare2GRAM100GHardDisk2.
ExperimentandanalysisBasedonMapReduceparallelimplementationofItem-basedcollaborativefilteringalgorithminparallelmodeexpansionrateperformancecomparisontest,selectthesizeofthedataset,respectively,intheefficiencyof1-8nodesrunning.
Theexperimentalresultsareshownbelow:Figure3PerformanceTestChartFigure3isbasedonMapReduceparallelimplementationofitembasedcollaborativefilteringalgorithmcantestchart,theXaxisisthenumberofclients,they-axisistheresponsetimeofthesystem.
TheexperimentalresultsshowthatbasedonMapReduceparallelimplementationofitembasedcollaborativefilteringalgorithmperformancecomparedtothetraditionalrecommendationalgorithmissignificantlyimproved.
ConclusionInthispaper,anewalgorithmofcollaborativefilteringalgorithmbasedonMapReduceisproposed.
Theexperimentresultsshowthatthenewalgorithmhashighefficiencyandcanachievehighperformanceatalowcost.
Butinthispaper,theuserclusteringiscompletedonthebasisoftheuserwithasmallnumberofattributes,forhighdimensionalattributesoftheusergroups,butalsotodofurtherresearch.
Inadditiontothenewalgorithminthispaperhasbeenputforward,wewillcontinuetoimprovetheexperimentalmethod,andconstantlyimprovetheaccuracyoftherecommendationalgorithm.
References[1]Chenruming,Challenges,valuesandcopingstrategiesintheeraofbigdata[J].
MobileCommunications.
2012(17):14-15.
[2]SunLingfang,ZhangJing.
ElectronicrecommendationmechanismbasedonRFMmodelandcollaborativefiltering[J].
JournalofJiangsuUniversityofScienceandTechnology(NaturalScienceEdition).
2010,24(3):285-289.
[3]LIGai,PANRong.
etCollaborativefilteringalgorithmparallelizeresearchbasedonlargedatasetsa[J].
ComputerEngineeringandDesign,2012,33(6):2437-2441.
[4]LIWenhai;XUShuren;DesignandimplementationofrecommendationsystemforE-commerceonHadoop[J].
ComputerEngineeringandDesign,2014(35):131-136.
[5]SUNTianhao,LIAnnenget.
ResearchonDistributedCollaborativeFilteringRecommendationAlgorithmBasedonHadoop[J].
ComputerEngineeringandApplications,2014,51(15):124:128[6]XieXuelian,LiLanyou.
ResearchonParallelK-meansAlgorithmBasedonCloundComputingPlatform[J].
ComputerMeasurement&Control,2014,22(5):1510-1512.
[7]YanCun,JiGenlin.
DesignandImplementationofItem-BasedParallelCollaborativeFilteringAlgorithm[J].
JOURNALOFNANJINGNORMALUNIVERSITY(NaturalScienceEdition),2014,37(1):71-75.
[8]WAGNFei,QinXiaolin.
Algorithmfork-meansBasedonDataStreaminCloudComputing[J].
ComputerScience,2015,42(11):235:239.
comKeywords:RecommendationsystemparallelcomputingClusteringAbstract.
TraditionalcollaborativefilteringalgorithmbasedonitemandK-meansclusteringalgorithmarestudied,theparallelalgorithmofcollaborativefilteringItem-basedonMapReduceisproposedbyusingMapReduceprogrammingmodel.
Thealgorithmismainlydividedintotwosteps,onestepisK-Meansalgorithmclusteringforusers,anotherstepistheparallelItem-basedalgorithmforclusteringuserrecommendation.
Experimentalresultsshowthatthealgorithmhasobtainedverygoodeffect,improvedtherunningspeedandexecutionefficiency,theimprovedalgorithmismuchsuitableforprocessingbigdata.
IntroductionBigdatausuallyincludesdatasetswithsizesbeyondtheabilityofcommonlyusedsoftwaretoolstocapture,curate,manage,andprocessdatawithinatolerableelapsedtime.
Bigdataishighvolume,highvelocity,and/orhighvarietyinformationassetsthatrequirenewformsofprocessingtoenableenhanceddecisionmaking,insightdiscoveryandprocessoptimization.
Volumemeansbigdatadoesn'tsample;itjustobservesandtrackswhathappens;Velocitymeansbigdataisoftenavailableinreal-time;Varietymeansbigdatadrawsfromtext,images,audio,video;plusitcompletesmissingpiecesthroughdatafusion[1].
Therefore,thebigdatamustbethroughthecomputerstatistics,comparison,analysisofthedatacanbetheobjectiveresults.
Nowelectroniccommercesystemsofeverytransaction,everyinputandeverysearchcanasdata,datathroughthecomputersystemtodothescreening,sorting,analysis,sothattheanalysisresultsisnotonlyanobjectiveconclusion,moreabletohelpbusinessprovidedthedecision-makingofenterprisesandalsocollectedusefuldatacanalsobereasonableplanning,activelyguidethedevelopmentoflargerpowerconsumption,andmoreeffectivemarketingandpromotion.
Withtheincreasingamountofdataintheelectroniccommercesystem,theneedforalargenumberofdatadepthanalysisisincreasinglyurgent.
Therefore,theuseofasimpleandhighscalabilityoftheprogramfortheanalysisofproductrecommendationisparticularlyimportant.
Atpresentdomesticmanyecommercesitesusecollaborativefilteringalgorithm,suchasAmazon,Dangdang,collaborativefilteringalgorithmismainlydividedintobasedontheitemsofthecollaborativefilteringalgorithmanduserbasedcollaborativefilteringalgorithm.
Basedonitemsofcollaborativefilteringalgorithmistomeasurethesimilaritybetweenitemsaccordingtotheuser'spreferences,donotneedtoconsidertheitemspecificcontentfeatures,sothealgorithmismainlyusedine-commercerecommendationandmovierecommendationdomain,thealgorithmwhileinthefieldofelectroniccommercerecommendationhasbeenacertaindegreeofsuccess.
Butinmassivedataarerecommendedwhenthedataisrecommendedperformanceisnothighandthedatainformationlackofsharingandextendedtheleadtothehardwarerequirementscomparedhigherinherentshortcomingsmakeitdidnotreceiveapromotionandsupportofenterpriseelectroniccommerce[2].
SoifweuseMapReducetoachievedistributedparallelcomputing,itwillgreatlyimprovetheefficiencyandperformanceofthealgorithm,andpromotethefurtherdevelopmentofthealgorithm[3-4].
Basedontheitemsofthecollaborativefilteringalgorithmisaccordingtoitemsimilarityanduserhistoryaccessrecordrecommendedtotheusertogeneratealistofitems,buttherearesomesmallproblems,suchasdatasparsityproblemandwhenthemassofusersandthenumberofitems,theuserbehaviorandrecorddatawillgreatly,andthealgorithmforcomputingitemswithsimilarmatrixcostgreatly,algorithmefficiencyandperformancewillgreatlyreduce.
Aimingattheaboveproblems,theclusteringalgorithmhasalsobeenappliedtoacollaborativefilteringalgorithmbasedonitem,themassiveuserclusteringanalysis,soitcanavoidthequestioncarefully,foreachusertorecommendoperation.
Thefirstshoppinguserswithsimilarinterestsintoauserclass,withaclusterofuserrecommendedgoodsarethesame.
Thesecondistoreducethemassiveuserdimensionsbecomedozensofclusteringlimited,thetimecomplexityencounteredabottleneck,andtheparallelclusteringalgorithmusingMapReduceistheeffectivewaytosolvethebottleneck[5].
MapReduceisadistributedprogrammingmodelframeworkonHadoopplatform,intheconditionofnotfamiliarwiththeunderlyingdetailsofthedistributedimplementationoftheimplementationoftheprogram[6].
TheMapReduceasparallelcomputingprogrammingmodel,firstofalltousersofMapReducebasedparallelclusteringandaccordingtotheresultsofuserclustering,ineveryuserclassusingtheMapReduceparallelcollaborativefilteringrecommendation,eventuallygiveusersareasonablepersonalizedcommodityrecommendationlist.
Therunningtimeofdifferentnodesinthequantitativedataiscomparedwiththenewalgorithm.
Theresultsshowthatthedataprocessingperformanceoftheproposedalgorithmisgreatlyimproved.
TheprincipleofMapReduceprogrammingmodelMapReduceisinHadoopplatformbyusingparallelcomputingprogrammingmodel,thetechniqueisproposedbyGoogleforatypicaldistributedparallelprogrammingmodel,theuserintheMapReducemodeldevelopthemapandreducefunctions,canrealizetheparallelprocessing.
Mapwillberesponsiblefordatadispersion,Reduceisresponsiblefordataaggregation.
UsersonlyneedtoachieveMapandReducetwointerface,youcancompletethecalculationofTBleveldata.
BecauseoftheMapReducemodel,thedetailsoftheparallelandfault-tolerantprocessingareencapsulated,whichmakesprogrammingveryeasytoimplement.
MapReduceparallelcalculationisdividedintotwoparts,thefirststepisinitializingtheoriginalinputdatafileandthedatasetisdividedintoapluralityofacertainsizeofdatablock,facilitateparallelcomputing;thesecondstepistostartthemapandreducefunctionsalgorithmofparallelcomputing,finallyproducedthefinalresult.
Figure1ParallelflowchartofMapReduceKeytechnologyresearchandImplementation1.
ThebasicideaofthetraditionalcollaborativefilteringalgorithmbasedonItem-basedThetraditionalbasedonitemsofcollaborativefilteringalgorithmthebasicideaisdividedintothreeparts,thefirstpartistocomputethesimilaritybetweenitems,commonsimilaritycalculationmethodwithcosinesimilarity,Pearsoncorrelationcoefficient,Tanmotocoefficientcorrelationof.
ThispaperselectstheEuclideansimilarityalgorithm,asfollows:TheassumptionisthatthereisavectorXandavectorY:X=(1x,2x,3x),Y=(1y,2y,3y),UsingtheEuclideansimilarityalgorithmtocalculatethesimilaritybetweenXandYSvector(x,y)formulaisasfollows[7]:1(,)1(,)Sxydxy=+(1)Where(,)dxyisthedistancebetweenthevectorXandY,thecalculationformulaisasfollows:222231123(dxyxyyyxx2)Thesecondpartistocalculatetheuserratingsmatrixontheitemsofthegoodsaccordingtothesimilaritymatrix;thethirdpartistheitemsimilaritymatrixWandtheusersoftheitemscorematrixmultiplicationtoobtaintherecommendationresults.
TraditionalItem-Basedcollaborativefilteringrecommendationalgorithmbasedonitemisthestagethataffectstheperformanceofthealgorithm.
Ifthenumberofusersisn,thenumberofcommodityitemsism,thetimecomplexityoffindingalltheitemsinthenprojectisO(2m),thetotalsearchspaceisnusers,sothetimecomplexityofcomputingsimilarityisO(2nm).
Sowhencalculatingthesimilaritymatrixofitems,itisindependentofthesimilaritybetweenthecalculatedandtheotherpairofitemstoaproject,soitispossibletocalculatethesimilaritymatrix.
2.
AnewalgorithmofItem-basedbasedonMapReduceThenewalgorithmismainlydividedintotwosteps;thefirststepistheMapReduceimplementationofK-Meansalgorithmbasedonclusteringofusers.
ThesecondstepistoachievetheparallelrecommendationalgorithmofItem-basedonMapReduce,theproductofuserclusteringrecommendation.
2.
1ThenewalgorithmK-MeansbasedonMapReduceThebasicideaofthetraditionalK-meansclusteringalgorithm:fromMdataobjectsinarbitrarychoiceofKobjectsastheinitialclustercenters;fortherestoftheotherobjects,accordingtotheirdistanceandtheclustercenters,respectively,theyallocatedtoitsmostsimilarclustering;thencalculateeachreceivedanewclusteringalgorithmclusteringcenter;keeprepeatingtheprocessuntilnochangesinacore.
Inthek-meansalgorithmtocalculatethedistancebetweendataobjectsandclustercentersisthemosttime-consumingoperation.
ThedataobjectandKclustercenterdistancecomparisonatthesametime,datafromotherobjectscanalsobecomparedwiththeKdistanceofthecenterofcluster,sotheoperationcanbeparallelized[8]BasedonMapReduceparallelimplementationofK-meansalgorithmcanimprovethespeedoftheclusteringalgorithm,isdividedintothreesteps:thefirststep:themapfunction,foreverypointcalculationrecentlythecenterdistanceandthecorrespondingtothenearestclustercenter.
Thesecondstep:Combinefunction,justcompletedtheMapmachineonthemachinearecompletedwiththesamepointoftheclusterpointofsummation,reducetheamountofcommunicationandcomputationofReduceoperation.
ThisstepisthekeytotheuseofCombinefunctiononthemachineonthefirstofthesameclustermerge,reducedtotheReducefunctionofthetransferandtheamountofcomputation.
Thethirdstep:theReducefunction,theintermediatedataofeachclustercenterwillbeformedandthenewclustercentercanbeobtained.
Eachiterationisrepeatedonthethreestep.
Figure2ParallelFlowChartofK-meansAlgorithmbasedonMapReduce2.
2thecollaborativefilteringalgorithmbasedonMapReduceforparallelimplementationofItem-basedBasedonthesimilaritycalculationformulamentionedabove(1),thispaperpresentsacollaborativefilteringrecommendationalgorithmbasedonMapReduce.
Algorithm1ThecollaborativefilteringrecommendationalgorithmbasedonMapReduceINPUT:Userinformationfile,Iteminformationfile,IntendeduserOUTPUT:IntendeduserrecommendedlistTheprocessisasfollows:Step1:Transformingtheuservectorintoanitemvector;Step2:Parallelcalculationofthesimilaritybetweenitems;thecalculationofthesimilaritybetweenitemsaccordingtotheformula(2)tocalculate;Step3:Similaritymatrixofparallelcomputingobjects;Step4:Parallelcomputinguserratingmatrix;inthecalculationoftheuser'sscoringmatrix,iftheuserisnotontheitemstoomuch,thenthedefaultscoreis1;Step5:Theresultsobtainedbythemultiplicationofthesimilaritymatrixofparallelcomputingobjectsandtheuser'sscorematrixarerecommended.
Experimentalresultanalysis1.
experimentalenvironmentThesimulationexperimentusingVMware_Workstation_10.
0.
3,virtualizationsoftwaretovirtualHadoopcloudplatform.
EightvirtualmachinesareinstalledonthevirtualHadoopcloudplatform,andaHadoopclusterenvironmentisbuiltontheseeightvirtualmachines.
OneofthevirtualmachineasagoodJobTrackernodeNameNode,theothersevenvirtualmachinesdeployedTaskTrackerandDataNode.
Thesemachinesareinthesamelocalareanetwork.
Theexperimentuseseightsetsofvirtualmachinehardwareconfigurationandsoftwareconfigurationasshownintable1:Table1HadoopClusterConfigurationOSCentos6.
4JDKVersion1.
6.
0Hadoop1.
1.
2HardWare2GRAM100GHardDisk2.
ExperimentandanalysisBasedonMapReduceparallelimplementationofItem-basedcollaborativefilteringalgorithminparallelmodeexpansionrateperformancecomparisontest,selectthesizeofthedataset,respectively,intheefficiencyof1-8nodesrunning.
Theexperimentalresultsareshownbelow:Figure3PerformanceTestChartFigure3isbasedonMapReduceparallelimplementationofitembasedcollaborativefilteringalgorithmcantestchart,theXaxisisthenumberofclients,they-axisistheresponsetimeofthesystem.
TheexperimentalresultsshowthatbasedonMapReduceparallelimplementationofitembasedcollaborativefilteringalgorithmperformancecomparedtothetraditionalrecommendationalgorithmissignificantlyimproved.
ConclusionInthispaper,anewalgorithmofcollaborativefilteringalgorithmbasedonMapReduceisproposed.
Theexperimentresultsshowthatthenewalgorithmhashighefficiencyandcanachievehighperformanceatalowcost.
Butinthispaper,theuserclusteringiscompletedonthebasisoftheuserwithasmallnumberofattributes,forhighdimensionalattributesoftheusergroups,butalsotodofurtherresearch.
Inadditiontothenewalgorithminthispaperhasbeenputforward,wewillcontinuetoimprovetheexperimentalmethod,andconstantlyimprovetheaccuracyoftherecommendationalgorithm.
References[1]Chenruming,Challenges,valuesandcopingstrategiesintheeraofbigdata[J].
MobileCommunications.
2012(17):14-15.
[2]SunLingfang,ZhangJing.
ElectronicrecommendationmechanismbasedonRFMmodelandcollaborativefiltering[J].
JournalofJiangsuUniversityofScienceandTechnology(NaturalScienceEdition).
2010,24(3):285-289.
[3]LIGai,PANRong.
etCollaborativefilteringalgorithmparallelizeresearchbasedonlargedatasetsa[J].
ComputerEngineeringandDesign,2012,33(6):2437-2441.
[4]LIWenhai;XUShuren;DesignandimplementationofrecommendationsystemforE-commerceonHadoop[J].
ComputerEngineeringandDesign,2014(35):131-136.
[5]SUNTianhao,LIAnnenget.
ResearchonDistributedCollaborativeFilteringRecommendationAlgorithmBasedonHadoop[J].
ComputerEngineeringandApplications,2014,51(15):124:128[6]XieXuelian,LiLanyou.
ResearchonParallelK-meansAlgorithmBasedonCloundComputingPlatform[J].
ComputerMeasurement&Control,2014,22(5):1510-1512.
[7]YanCun,JiGenlin.
DesignandImplementationofItem-BasedParallelCollaborativeFilteringAlgorithm[J].
JOURNALOFNANJINGNORMALUNIVERSITY(NaturalScienceEdition),2014,37(1):71-75.
[8]WAGNFei,QinXiaolin.
Algorithmfork-meansBasedonDataStreaminCloudComputing[J].
ComputerScience,2015,42(11):235:239.
- leadcentos6.0相关文档
- HSLT72A3200centos6.0
- AMDcentos6.0
- insightscentos6.0
- goalscentos6.0
- 虚拟centos6.0
- 安装centos6.0
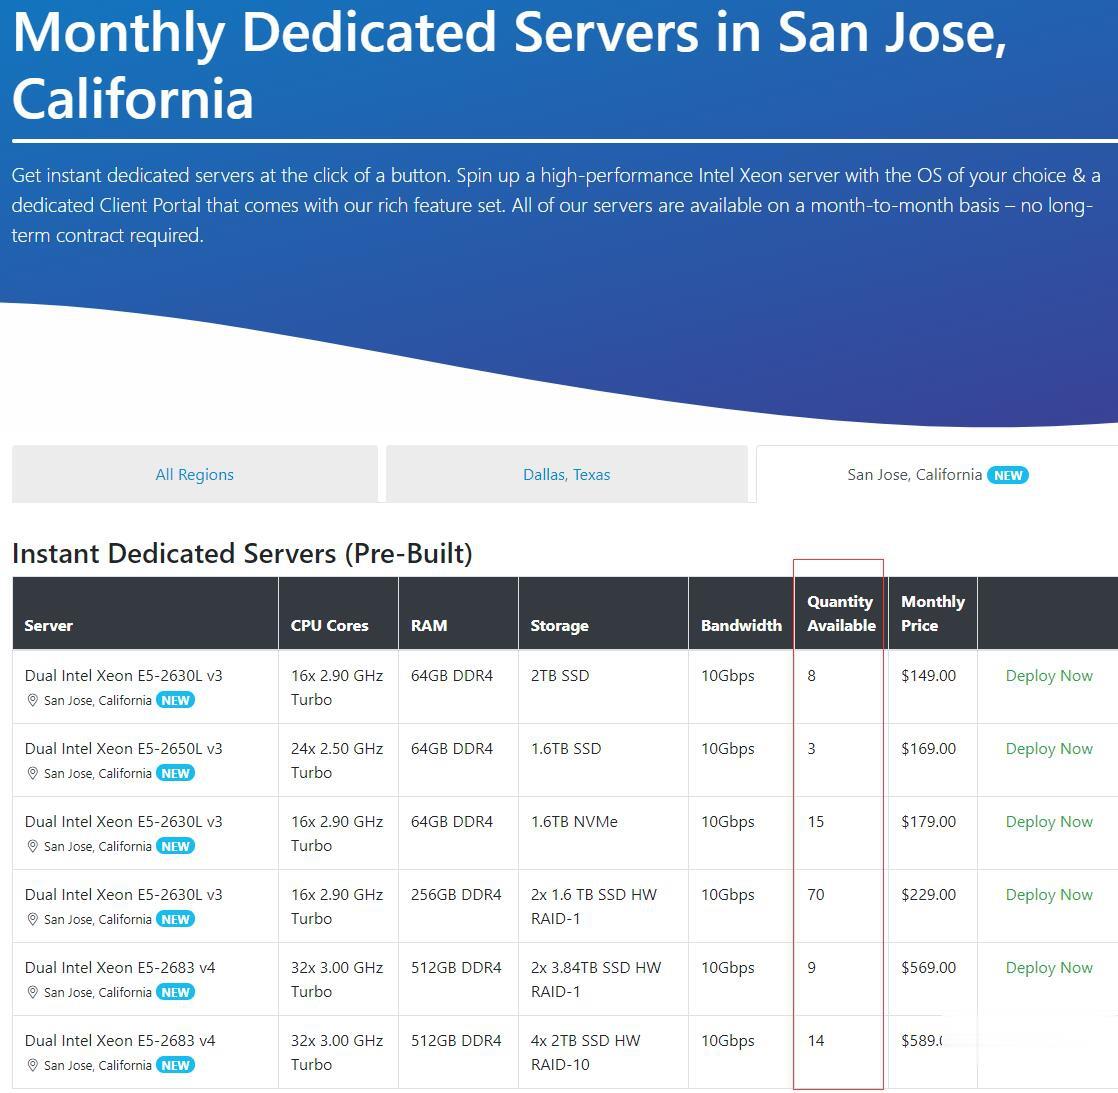
Spinservers:美国圣何塞机房少量补货/双E5/64GB DDR4/2TB SSD/10Gbps端口月流量10TB/$111/月
Chia矿机,Spinservers怎么样?Spinservers好不好,Spinservers大硬盘服务器。Spinservers刚刚在美国圣何塞机房补货120台独立服务器,CPU都是双E5系列,64-512GB DDR4内存,超大SSD或NVMe存储,数量有限,机器都是预部署好的,下单即可上架,无需人工干预,有需要的朋友抓紧下单哦。Spinservers是Majestic Hosting So...
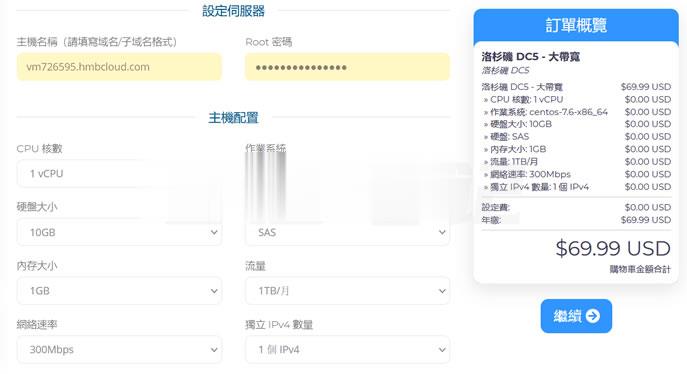
半月湾hmbcloud升级500Mbps带宽,原生VPS,$4.99/月
关于半月湾HMBCloud商家之前也有几篇那文章介绍过这个商家的产品,对于他们家的其他产品我都没有多加留意,而是对他们家的DC5机房很多人还是比较喜欢的,这个比我们有些比较熟悉的某商家DC6 DC9机房限时,而且半月湾HMBCloud商家是相对便宜的。关于半月湾DC5机房的方案选择和介绍:1、半月湾三网洛杉矶DC5 CN2 GIA同款DC6 DC9 1G内存 1TB流量 月$4.992、亲测选择半...
racknerd:美国大硬盘服务器,$599/月,Ryzen7-3700X/32G内存/120gSSD+192T hdd
racknerd当前对美国犹他州数据中心的大硬盘服务器(存储服务器)进行低价促销,价格跌破眼镜啊。提供AMD和Intel两个选择,默认32G内存,120G SSD系统盘,12个16T HDD做数据盘,接入1Gbps带宽,每个月默认给100T流量,5个IPv4... 官方网站:https://www.racknerd.com 加密数字货币、信用卡、PayPal、支付宝、银联(卡),可以付款! ...
centos6.0为你推荐
-
硬盘的工作原理简述下硬盘的工作原理?同ip网站同IP的两个网站,做单向链接,会不会被K掉??5xoy.comhttp www.05eee.comwww.se333se.com米奇网www.qvod333.com 看电影的效果好不?www.45gtv.com登录农行网银首页www.abchina.com,baqizi.cc誰知道,最近有什麼好看的電視劇www.mfav.org海关编码在线查询http://www.ccpit.org.cbk乐乐bk乐乐和CK是什么关系?鹤城勿扰非诚勿扰 怀化小伙 杨荣是哪一期盗车飞侠侠盗飞车罪恶都市全部秘籍ps手柄版的