proposedto
destoon 时间:2021-02-05 阅读:()
LearningBayesianNetworkswithThousandsofVariablesMauroScanagattaIDSIA,SUPSI,USILugano,Switzerlandmauro@idsia.
chCassioP.
deCamposQueen'sUniversityBelfastNorthernIreland,UKc.
decampos@qub.
ac.
ukGiorgioCoraniIDSIA,SUPSI,USILugano,Switzerlandgiorgio@idsia.
chMarcoZaffalonIDSIALugano,Switzerlandzaffalon@idsia.
chAbstractWepresentamethodforlearningBayesiannetworksfromdatasetscontainingthousandsofvariableswithouttheneedforstructureconstraints.
Ourapproachismadeoftwoparts.
Therstisanovelalgorithmthateffectivelyexploresthespaceofpossibleparentsetsofanode.
Itguidestheexplorationtowardsthemostpromisingparentsetsonthebasisofanapproximatedscorefunctionthatiscomputedinconstanttime.
Thesecondpartisanimprovementofanexistingordering-basedalgorithmforstructureoptimization.
Thenewalgorithmprovablyachievesahigherscorecomparedtoitsoriginalformulation.
Ournovelapproachconsistentlyoutperformsthestateoftheartonverylargedatasets.
1IntroductionLearningthestructureofaBayesiannetworkfromdataisNP-hard[2].
Wefocusonscore-basedlearning,namelyndingthestructurewhichmaximizesascorethatdependsonthedata[9].
Severalexactalgorithmshavebeendevelopedbasedondynamicprogramming[12,17],branchandbound[7],linearandintegerprogramming[4,10],shortest-pathheuristic[19,20].
Usuallystructurallearningisaccomplishedintwosteps:parentsetidenticationandstructureoptimization.
Parentsetidenticationproducesalistofsuitablecandidateparentsetsforeachvariable.
Structureoptimizationassignsaparentsettoeachnode,maximizingthescoreoftheresultingstructurewithoutintroducingcycles.
Theproblemofparentsetidenticationisunlikelytoadmitapolynomial-timealgorithmwithagoodqualityguarantee[11].
Thismotivatesthedevelopmentofeffectivesearchheuristics.
Usuallyhoweveronedecidesthemaximumin-degree(numberofparentspernode)kandthensimplycom-putesthescoreofallparentsets.
Atthatpointoneperformsstructuraloptimization.
AnexceptionisthegreedysearchoftheK2algorithm[3],whichhashoweverbeensupersededbythemoremodernapproachesmentionedabove.
Ahigherin-degreeimpliesalargersearchspaceandallowsachievingahigherscore;howeveritalsorequireshighercomputationaltime.
Whenchoosingthein-degreetheusermakesatrade-offbetweenthesetwoobjectives.
Howeverwhenthenumberofvariablesislarge,thein-degreeisIstitutoDalleMolledistudisull'IntelligenzaArticiale(IDSIA)ScuolauniversitariaprofessionaledellaSvizzeraitaliana(SUPSI)Universit`adellaSvizzeraitaliana(USI)1generallysettoasmallvalue,toallowtheoptimizationtobefeasible.
Thelargestdatasetanalyzedin[1]withtheGobnilp1softwarecontains413variables;itisanalyzedsettingk=2.
In[5]Gobnilpisusedforstructurallearningwith1614variables,settingk=2.
Theseareamongthelargestexamplesofscore-basedstructurallearningintheliterature.
Inthispaperweproposeanalgorithmthatperformsapproximatedstructurelearningwiththousandsofvariableswithoutconstraintsonthein-degree.
Itisconstitutedbyanovelapproachforparentsetidenticationandanovelapproachforstructureoptimization.
Asforparentsetidenticationweproposeananytimealgorithmthateffectivelyexploresthespaceofpossibleparentsets.
Itguidestheexplorationtowardsthemostpromisingparentsets,exploitinganapproximatedscorefunctionthatiscomputedinconstanttime.
Asforstructureoptimization,weextendtheordering-basedalgorithmof[18],whichprovidesaneffectiveapproachformodelselectionwithreducedcomputationalcost.
Ouralgorithmisguaranteedtondasolutionbetterthanorequaltothatof[18].
Wetestourapproachondatasetscontaininguptotenthousandvariables.
Asaperformanceindica-torweconsiderthescoreofthenetworkfound.
Ourparentsetidenticationapproachoutperformsconsistentlytheusualapproachofsettingthemaximumin-degreeandthencomputingthescoreofallparentsets.
OurstructureoptimizationapproachoutperformsGobnilpwhenlearningwithmorethan500nodes.
Allthesoftwareanddatasetsusedintheexperimentsareavailableonline.
2.
2StructureLearningofBayesianNetworksConsidertheproblemoflearningthestructureofaBayesianNetworkfromacompletedatasetofNinstancesD={D1,.
.
.
,DN}.
ThesetofncategoricalrandomvariablesisX={X1,.
.
.
,Xn}.
ThegoalistondthebestDAGG=(V,E),whereVisthecollectionofnodesandEisthecollectionofarcs.
EcanbedenedasthesetofparentsΠ1,.
.
.
,Πnofeachvariable.
DifferentscorescanbeusedtoassessthetofaDAG.
WeadopttheBIC,whichasymptoticallyapproximatestheposteriorprobabilityoftheDAG.
TheBICscoreisdecomposable,namelyitisconstitutedbythesumofthescoresoftheindividualvariables:BIC(G)==ni=1BIC(Xi,Πi)=ni=1π∈|Πi|x∈|Xi|Nx,πlogθx|πlogN2(|Xi|1)(|Πi|),whereθx|πisthemaximumlikelihoodestimateoftheconditionalprobabilityP(Xi=x|Πi=π),andNx,πrepresentsthenumberoftimes(X=x∧Πi=π)appearsinthedataset,and|·|indicatesthesizeoftheCartesianproductspaceofthevariablesgivenasarguments(insteadofthenumberofvariables)suchthat|Xi|isthenumberofstatesofXiand||=1.
Exploitingdecomposability,werstidentifyindependentlyforeachvariablealistofcandidateparentsets(parentsetidentication).
Thenbystructureoptimizationweselectforeachnodetheparentsetthatyieldsthehighestscorewithoutintroducingcycles.
3ParentsetidenticationForparentsetidenticationusuallyoneexploresallthepossibleparentsets,whosenumberhoweverincreasesasO(nk),wherekdenotesthemaximumin-degree.
Pruningrules[7]donotconsiderablyreducethesizeofthisspace.
Usuallytheparentsetsareexploredinsequentialorder:rstalltheparentsizeofsizeone,thenalltheparentsetsofsizetwo,andsoon,uptosizek.
Werefertothisapproachassequentialordering.
Ifthesolveradoptedforstructuraloptimizationisexact,thisstrategyallowstondthegloballyoptimumgraphgiventhechosenvalueofk.
Inordertodealwithalargenumberofvariablesitishowevernecessarysettingalowin-degreek.
Forinstance[1]adoptsk=2whendealingwiththelargestdataset(diabetes),whichcontains413variables.
In[5]Gobnilpisusedforstructurallearningwith1614variables,againsettingk=2.
Ahighervalueofkwouldmakethestructural1http://www.
cs.
york.
ac.
uk/aig/sw/gobnilp/2http://blip.
idsia.
ch2learningnotfeasible.
Yetalowkimpliesdroppingalltheparentsetswithsizelargerthank.
Someofthempossiblyhaveahighscore.
In[18]itisproposedtoadoptthesubsetΠcorrofthemostcorrelatedvariableswiththechildrenvariable.
Then[18]consideronlyparentsetswhicharesubsetsofΠcorr.
Howeverthisapproachisnotcommonlyadopted,possiblybecauseitrequiresspecifyingthesizeofΠcorr.
Indeed[18]acknowledgestheneedforfurtherinnovativeapproachesinordertoeffectivelyexplorethespaceoftheparentsets.
Weproposetwoanytimealgorithmstoaddressthisproblem.
Therstisthesimplest;wecallitgreedyselection.
Itstartsbyexploringalltheparentsetsofsizeoneandaddingthemtoalist.
Thenitrepeatsthefollowinguntiltimeisexpired:popsthebestscoringparentsetΠfromthelist,exploresallthesupersetsobtainedbyaddingonevariabletoΠ,andaddsthemtothelist.
Notethatingeneraltheparentsetschosenattwoadjoiningsteparenotrelatedtoeachother.
Thesecondapproach(independenceselection)adoptsamoresophisticatedstrategy,asexplainedinthefollowing.
3.
1ParentsetidenticationbyindependenceselectionIndependenceselectionusesanapproximationoftheactualBICscoreofaparentsetΠ,whichwedenoteasBIC,toguidetheexplorationofthespaceoftheparentsets.
TheBICofaparentsetconstitutedbytheunionoftwonon-emptyparentsetsΠ1andΠ2isdenedasfollows:BIC(X,Π1,Π2)=BIC(X,Π1)+BIC(X,Π2)+inter(X,Π1,Π2),(1)withΠ1∪Π2=Πandinter(X,Π1,Π2)=logN2(|X|1)(|Π1|+|Π2||Π1||Π2|1)BIC(X,).
IfwealreadyknowBIC(X,Π1)andBIC(X,Π2)frompreviouscalculations(andweknowBIC(X,)),thenBICcanbecomputedinconstanttime(withrespecttodataaccesses).
WethusexploitBICtoquicklyestimatethescoreofalargenumberofcandidateparentsetsandtodecidetheordertoexplorethem.
WeprovideaboundforthedifferencebetweenBIC(X,Π1,Π2)andBIC(X,Π1∪Π2).
Tothisend,wedenotebyiitheInteractionInformation[14]:ii(X;Y;Z)=I(X;Y|Z)I(X;Y),namelythedifferencebetweenthemutualinformationofXandYconditionalonZandtheunconditionalmutualinformationofXandY.
Theorem1.
LetXbeanodeofGandΠ=Π1∪Π2beaparentsetforXwithΠ1∩Π2=andΠ1,Π2non-empty.
ThenBIC(X,Π)=BIC(X,Π1,Π2)+N·ii(Π1;Π2;X),whereiiistheInteractionInformationestimatedfromdata.
Proof.
BIC(X,Π1∪Π2)BIC(X,Π1,Π2)=BIC(X,Π1∪Π2)BIC(X,Π1)BIC(X,Π2)inter(X,Π1,Π2)=x,π1,π2Nx,π1,π2logθx|π1,π2log(θx|π1θx|π2)+xNxlogθx=x,π1,π2Nx,π1,π2logθx|π1,π2logθx|π1θx|π2θx=x,π1,π2Nx,π1,π2logθx|π1,π2θxθx|π1θx|π2=x,π1,π2N·θx,π1,π2logθπ1,π2|xθπ1θπ2θπ1|xθπ2|xθπ1,π2=Nx,π1,π2θx,π1,π2logθπ1,π2|xθπ1|xθπ2|xπ1,π2θπ1,π2logθπ1,π2θπ1θπ2=N·(I(Π1;Π2|X)I(Π1;Π2))=N·ii(Π1;Π2;X),whereI(·)denotesthe(conditional)mutualinformationestimatedfromdata.
Corollary1.
LetXbeanodeofG,andΠ=Π1∪Π2beaparentsetofXsuchthatΠ1∩Π2=andΠ1,Π2non-empty.
Then|BIC(X,Π)BIC(X,Π1,Π2)|≤Nmin{H(X),H(Π1),H(Π2)}.
Proof.
Theorem1statesthatBIC(X,Π)=BIC(X,Π1,Π2)+N·ii(Π1;Π2;X).
Wenowdeviseboundsforinteractioninformation,recallingthatmutualinformationandconditionalmutualinfor-mationarealwaysnon-negativeandachievetheirmaximumvalueatthesmallestentropyHoftheir3argument:H(Π2)≤I(Π1;Π2)≤ii(Π1;Π2;X)≤I(Π1;Π2|X)≤H(Π2).
ThetheoremisprovenbysimplypermutingthevaluesΠ1;Π2;Xintheiiofsuchequation.
Sinceii(Π1;Π2;X)=I(Π1;Π2|X)I(Π1;Π2)=I(X;Π1|Π2)I(X;Π1)=I(Π2;X|Π1)I(Π2;X),theboundsforiiarevalid.
Weknowthat0≤H(Π)≤log(|Π|)foranysetofnodesΠ,hencetheresultofCorollary1couldbefurthermanipulatedtoachieveaboundforthedifferencebetweenBICandBICofatmostNlog(min{|X|,|Π1|,|Π2|}).
However,Corollary1isstrongerandcanstillbecomputedefcientlyasfollows.
WhencomputingBIC(X,Π1,Π2),weassumedthatBIC(X,Π1)andBIC(X,Π2)hadbeenprecomputed.
Assuch,wecanalsohaveprecomputedthevaluesH(Π1)andH(Π2)atthesametimeastheBICscoreswerecomputed,withoutanysignicantincreaseofcomplexity(whencomputingBIC(X,Π)foragivenΠ,justusethesameloopoverthedatatocomputeH(Π)).
Corollary2.
LetXbeanodeofG,andΠ=Π1∪Π2beaparentsetforthatnodewithΠ1∩Π2=andΠ1,Π2non-empty.
IfΠ1⊥⊥Π2,thenBIC(X,Π1∪Π2)≥BIC(X,Π1∪Π2).
IfΠ1⊥⊥Π2|X,thenBIC(X,Π1∪Π2)≤BIC(X,Π1∪Π2).
Iftheinteractioninformationii(Π1;Π2;X)=0,thenBIC(X,Π1∪Π2)=BIC(X,Π1,Π2).
Proof.
ItfollowsfromTheorem1consideringthatmutualinformationI(Π1,Π2)=0ifΠ1andΠ2areindependent,whileI(Π1,Π2|X)=0ifΠ1andΠ2areconditionallyindependent.
WenowdeviseanovelpruningstrategyforBICbasedontheboundsofCorollaries1and2.
Theorem2.
LetXbeanodeofG,andΠ=Π1∪Π2beaparentsetforthatnodewithΠ1∩Π2=andΠ1,Π2non-empty.
LetΠΠ.
IfBIC(X,Π1,Π2)+logN2(|X|1)|Π|>Nmin{H(X),H(Π1),H(Π2)},thenΠanditssupersetsarenotoptimalandcanbeignored.
Proof.
BIC(X,Π1,Π2)Nmin{H(X),H(Π1),H(Π2)}+logN2(|X|1)|Π|>0impliesBIC(Π)+logN2(|X|1)|Π|>0,andTheorem4of[6]prunesΠandallitssupersets.
Thuswecanefcientlycheckwhetherlargepartsofthesearchspacecanbediscardedbasedontheseresults.
WenotethatCorollary1andhenceTheorem2areverygenericinthechoiceofΠ1andΠ2,eventhoughusuallyoneofthemistakenasasingleton.
3.
2IndependenceselectionalgorithmWenowdescribethealgorithmthatexploitstheBICscoreinordertoeffectivelyexplorethespaceoftheparentsets.
Itusestwolists:(1)open:alistfortheparentsetstobeexplored,orderedbytheirBICscore;(2)closed:alistofalreadyexploredparentsets,alongwiththeiractualBICscore.
ThealgorithmstartswiththeBICoftheemptysetcomputed.
FirstitexploresalltheparentsetsofsizeoneandsavestheirBICscoreintheclosedlist.
Thenitaddstotheopenlisteveryparentsetofsizetwo,computingtheirBICscoresinconstanttimeonthebasisofthescoresavailablefromtheclosedlist.
Itthenproceedsasfollowsuntilallelementsinopenhavebeenprocessed,orthetimeisexpired.
ItextractsfromopentheparentsetΠwiththebestBICscore;itcomputesitsBICscoreandaddsittotheclosedlist.
ItthenlooksforallthepossibleexpansionsofΠobtainedbyaddingasinglevariableY,suchthatΠ∪Yisnotpresentinopenorclosed.
ItaddsthemtoopenwiththeirBIC(X,Π,Y)scores.
EventuallyitalsoconsidersalltheexploredsubsetsofΠ.
Itsafely[7]prunesΠifanyofitssubsetsyieldsahigherBICscorethanΠ.
Thealgorithmreturnsthecontentoftheclosedlist,prunedandorderedbytheBICscore.
Suchlistbecomesthecontentoftheso-calledcacheofscoresforX.
Theprocedureisrepeatedforeveryvariableandcanbeeasilyparallelized.
Figure1comparessequentialorderingandindependenceselection.
Itshowsthatindependenceselectionismoreeffectivethansequentialorderingbecauseitbiasesthesearchtowardsthehighest-scoringparentsets.
4StructureoptimizationThegoalofstructureoptimizationistochoosetheoverallhighestscoringparentsets(measuredbythesumofthelocalscores)withoutintroducingdirectedcyclesinthegraph.
Westartfromtheapproachproposedin[18](whichwecallordering-basedsearchorOBS),whichexploitsthefact45001,0002,0001,8001,6001,400IterationBIC(a)Sequentialordering.
5001,0002,0001,8001,6001,400IterationBIC(b)Indep.
selectionordering.
Figure1:Explorationoftheparentsetsspaceforagivenvariableperformedbysequentialorderingandindependenceselection.
Eachpointreferstoadistinctparentset.
thattheoptimalnetworkcanbefoundintimeO(Ck),whereC=ni=1ciandciisthenumberofelementsinthecacheofscoresofXi,ifanorderingoverthevariablesisgiven.
3Θ(k)isneededtocheckwhetherallthevariablesinaparentsetforXcomebeforeXintheordering(asimplearraycanbeusedasdatastructureforthischecking).
Thisimpliesworkingonthesearchspaceofthepossibleorderings,whichisconvenientasitissmallerthanthespaceofnetworkstructures.
Multipleorderingsaresampledandevaluated(differenttechniquescanbeusedforguidingthesampling).
ForeachsampledtotalorderingovervariablesX1,Xn,thenetworkisconsistentwiththeorderifXi:X∈Πi:XXi.
Anetworkconsistentwithagivenorderingautomaticallysatisestheacyclicityconstraint.
Thisallowsustochooseindependentlythebestparentsetofeachnode.
Moreover,foragiventotalorderingV1,Vnofthevariables,thealgorithmtriestoimprovethenetworkbyagreedysearchswappingprocedure:ifthereisapairVj,Vj+1suchthattheswappedorderingwithVjinplaceofVj+1(andviceversa)yieldsbetterscoreforthenetwork,thenthesenodesareswappedandthesearchcontinues.
Oneadvantageofthisswappingoverextrarandomorderingsisthatsearchingforitandupdatingthenetwork(ifagoodswapisfound)onlytakestimeO((cj+cj+1)·kn)(whichcanbespedupascjonlyisinspectedforparentssetscontainingVj+1,andcj+1isonlyprocessedifVj+1hasVjasparentinthecurrentnetwork),whileanewsampledorderingwouldtakeO(n+Ck)(theswappingapproachisusuallyfavourableifciis(n),whichisaplausibleassumption).
Weemphasizethattheuseofkhereissolewiththepurposeofanalyzingthecomplexityofthemethods,sinceourparentsetidenticationapproachdoesnotrelyonaxedvaluefork.
However,theconsistencyruleofOBSisquiterestricting.
Whileitsurelyrefusesallcyclicstructures,italsorulesoutsomeacycliconeswhichcouldbecapturedbyinterpretingtheorderinginaslightlydifferentmanner.
WeproposeanovelconsistencyruleforagivenorderingwhichprocessesthenodesinV1,VnfromVntoV1(OBScandoitinanyorder,asthelocalparentsetscanbechosenindependently)andwedenetheparentsetofVjsuchthatitdoesnotintroduceacycleinthecurrentpartialnetwork.
Thisallowsback-arcsintheorderingfromanodeVjtoitssuccessors,aslongasthisdoesnotintroduceacycle.
WecallthisideaacyclicselectionOBS(orsimplyASOBS).
Becauseweneedtocheckforcyclesateachstepofconstructingthenetworkforagivenordering,atarstglancethealgorithmseemstobeslower(timecomplexityofO(Cn)againstO(Ck)forOBS;notethisdifferenceisonlyrelevantasweintendtoworkwithlargevaluesn).
Surprisingly,wecanimplementitinthesameoveralltimecomplexityofO(Ck)asfollows.
1.
BuildandkeepaBooleansquarematrixmtomarkwhicharethedescendantsofnodes(m(X,Y)tellswhetherYisdescendantofX).
Startitallfalse.
2.
ForeachnodeVjintheorder,withj=n,1:(a)Gothroughtheparentsetsandpickthebestscoringoneforwhichallcontainedpar-entsarenotdescendantsofVj(thistakestimeO(cik)ifparentsetsarekeptaslists).
(b)BuildatodolistwiththedescendantsofVjfromthematrixrepresentationandasso-ciateanemptytodolisttoallancestorsofVj.
(c)StartthetodolistsoftheparentsofVjwiththedescendantsofVj.
(d)ForeachancestorXofVj(ancestorswillbeiterativelyvisitedbyfollowingadepth-rstgraphsearchprocedureusingthenetworkbuiltsofar;weprocessanodeafter3O(andΘ(·)shallbeunderstoodasusualasymptoticnotationfunctions.
5itschildrenwithnon-emptytodolistshavebeenalreadyprocessed;thesearchstopswhenallancestorsarevisited):i.
ForeachelementYinthetodolistofX,ifm(X,Y)istrue,thenignoreYandmoveon;otherwisesetm(X,Y)totrueandaddYtothetodoofparentsofX.
Letusanalyzethecomplexityofthemethod.
Step2atakesoveralltimeO(Ck)(alreadyconsideringtheouterloop).
Step2btakesoveralltimeO(n2)(alreadyconsideringtheouterloop).
Steps2cand2(d)iwillbeanalyzedbasedonthenumberofelementsonthetodolistsandthetimetoprocesstheminanamortizedway.
Notethatthetimecomplexityisdirectlyrelatedtothenumberofelementsthatareprocessedfromthetodolists(wecansimplylooktothemomentthattheyleavealist,astheirinclusioninthelistswillbeinequalnumber).
Wewillnowcountthenumberoftimesweprocessanelementfromatodolist.
Thisnumberisoverallbounded(overallexternalloopcycles)bythenumberoftimeswecanmakeacellofmatrixmturnfromfalsetotrue(whichisO(n2))plusthenumberoftimesweignoreanelementbecausethematrixcellwasalreadysettotrue(whichisatmostO(n)pereachVj,asthisisthemaximumnumberofdescendantsofVjandeachofthemcanfallintothiscategoryonlyonce,soagainthereareO(n2)timesintotal).
Inotherwords,eachelementbeingremovedfromatodolistiseitherignored(matrixalreadysettotrue)oranentryinthematrixofdescendantsischangedfromfalsetotrue,andthiscanonlyhappenO(n2)times.
HencethetotaltimecomplexityisO(Ck+n2),whichisO(Ck)foranyCgreaterthann2/k(averyplausiblescenario,aseachlocalcacheofavariableusuallyhasmorethann/kelements).
Moreover,wehavethefollowinginterestingpropertiesofthisnewmethod.
Theorem3.
Foragivenordering,thenetworkobtainedbyASOBShasscoreequalthanorgreatertothatobtainedbyOBS.
Proof.
ItfollowsimmediatelyfromthefactthattheconsistencyruleofASOBSgeneralizesthatofOBS,thatis,foreachnodeVjwithj=n,1,ASOBSallowsallparentsetsallowedbyOBSandalsoothers(containingback-arcs).
Theorem4.
ForagivenorderingdenedbyV1,VnandacurrentgraphGconsistentwith,ifOBSconsistencyruleallowstheswappingofVj,Vj+1andleadstoimprovingthescoreofG,thentheconsistencyruleofASOBSallowsthesameswappingandachievesthesameimprovementinscore.
Proof.
ItfollowsimmediatelyfromthefactthattheconsistencyruleofASOBSgeneralizesthatofOBS,sofromagivengraphG,ifaswappingispossibleunderOBSrules,thenitisalsopossibleunderASOBSrules.
5ExperimentsWecomparethreedifferentapproachesforparentsetidentication(sequential,greedyselectionandindependenceselection)andthreedifferentapproaches(Gobnilp,OBSandASOBS)forstructureoptimization.
Thisyieldsninedifferentapproachesforstructurallearning,obtainedbycombiningallthemethodsforparentsetidenticationandstructureoptimization.
NotethatOBShasbeenshownin[18]tooutperformothergreedy-tabusearchoverstructures,suchasgreedyhill-climbingandoptimal-reinsertion-searchmethods[15].
Weallowoneminutepervariabletoeachapproachforparentsetidentication.
Wesetthemaximumin-degreetok=6,ahighvaluethatallowslearningevencomplexstructures.
Noticethatournovelapproachdoesnotneedamaximumin-degree.
Wesetamaximumin-degreetoputourapproachanditscompetitorsonthesameground.
Oncecomputedthescoresoftheparentsetsweruneachsolver(Gobnilp,OBS,ASOBS)for24hours.
Foragivendatasetthecomputationisperformedonthesamemachine.
TheexplicitgoalofeachapproachforbothparentsetidenticationandstructureoptimizationistomaximizetheBICscore.
WethenmeasuretheBICscoreoftheBayesiannetworkseventuallyobtainedasperformanceindicator.
ThedifferenceintheBICscorebetweentwoalternativenetworksisanasymptoticapproximationofthelogarithmoftheBayesfactor.
TheBayesfactoristheratiooftheposteriorprobabilitiesoftwocompetingmodels.
LetusdenotebyBIC1,2=BIC1-BIC2thedifferencebetweentheBICscoreofnetwork1andnetwork2.
PositivevaluesofBIC1,2imply6DatasetnDatasetnDatasetnDatasetnAudio100Retail135MSWeb294Reuters-52889Jester100Pumsb-star163Book500C20NG910Netix100DNA180EachMovie500BBC1058Accidents111Kosarek190WebKB839Ad1556Table1:Datasetssortedaccordingtothenumbernofvariables.
evidenceinfavorofnetwork1.
Theevidenceinfavorofnetwork1isrespectively[16]{weak,positive,strong,verystrong}ifBIC1,2isbetween{0and2;2and6;6and10;beyond10}.
5.
1LearningfromdatasetsWeconsider16datasetsalreadyusedintheliteratureofstructurelearning,rstlyintroducedin[13]and[8].
Werandomlyspliteachdatasetintothreesubsetsofinstances.
Thisyields48datasets.
TheapproachesforparentsetidenticationarecomparedinTable2.
Foreachxedstructureop-timizationapproach,welearnthenetworkstartingfromthelistofparentsetscomputedbyinde-pendenceselection(IS),greedyselection(GS)andsequentialselection(SQ).
InturnweanalyzeBICIS,GSandBICIS,SQ.
ApositiveBICmeansthatindependenceselectionyieldsanetworkwithhigherBICscorethanthenetworkobtainedusinganalternativeapproachforparentsetiden-tication;viceversafornegativevaluesofBIC.
Inmostcases(seeTable2)BIC>10,implyingverystrongsupportforthenetworklearnedusingindependenceselection.
Wefurtheranalyzetheresultsthroughasign-test.
ThenullhypothesisofthetestisthattheBICscoreofthenetworklearnedunderindependenceselectionissmallerthanorequivalenttotheBICscoreofthenetworklearnedusingthealternativeapproach(greedyselectionorsequentialselectiondependingonthecase).
IfadatasetyieldsaBICwhichis{verynegative,stronglynegative,negative,neutral},itsupportsthenullhypothesis.
IfadatasetsyieldsaBICscorewhichis{positive,stronglypositive,extremelypositive},itsupportsthealternativehypothesis.
Underanyxedstructuresolver,thesigntestrejectsthenullhypothesis,providingsignicantevidenceinfavorofindependenceselection.
Inthefollowingwhenwefurthercitethesigntestwerefertosametypeofanalysis:thesigntestanalyzesthecountsoftheBICwhichareinfavorandagainstagivenmethod.
Asforstructureoptimization,ASOBSachieveshigherBICscorethanOBSinallthe48datasets,undereverychosenapproachforparentsetidentication.
TheseresultsconrmtheimprovementofASOBSoverOBS,theoreticallyproveninSection4.
InmostcasestheBICinfavorofASOBSislargerthan10.
ThedifferenceinfavorofASOBSissignicant(signtest,p10)443844304432Stronglypositive(610)212120211921Stronglypositive(610inmostcases.
TakeforinstanceGobnilpforstructureopti-mization.
ThenindependenceselectionyieldsaBIC>10in18/20caseswhencomparedtoGSandBIC>10in19/20caseswhencomparedtoSQ.
Similarresultsareobtainedusingtheothersolversforstructureoptimization.
StrongresultssupportalsoASOBSagainstOBSandGobnilp.
Undereveryapproachforparentsetidentication,BIC>10isobtainedin20/20caseswhencomparingASOBSandOBS.
ThenumberofcasesinwhichASOBSobtainsBIC>10whencomparedagainstGobnilprangesbetween17/20and19/20dependingontheapproachadoptedforparentsetselection.
ThesuperiorityofASOBSoverbothOBSandGobnilpissignicant(signtest,ptothou-sandsofnodeswithoutconstraintsonthemaximumin-degree.
ThecurrentresultsrefertotheBICscore,butinfuturethemethodologycouldbeextendedtootherscoringfunctions.
AcknowledgmentsWorkpartiallysupportedbytheSwissNSFgrantn.
200021146606/1.
4http://www.
bnlearn.
com/bnrepository/8References[1]M.
BartlettandJ.
Cussens.
IntegerlinearprogrammingfortheBayesiannetworkstructurelearningproblem.
ArticialIntelligence,2015.
inpress.
[2]D.
M.
Chickering,C.
Meek,andD.
Heckerman.
Large-samplelearningofBayesiannetworksishard.
InProceedingsofthe19stConferenceonUncertaintyinArticialIntelligence,UAI-03,pages124–133.
MorganKaufmann,2003.
[3]G.
F.
CooperandE.
Herskovits.
ABayesianmethodfortheinductionofprobabilisticnetworksfromdata.
MachineLearning,9(4):309–347,1992.
[4]J.
Cussens.
Bayesiannetworklearningwithcuttingplanes.
InProceedingsofthe27stCon-ferenceAnnualConferenceonUncertaintyinArticialIntelligence,UAI-11,pages153–160.
AUAIPress,2011.
[5]J.
Cussens,B.
Malone,andC.
Yuan.
IJCAI2013tutorialonoptimalalgorithmsforlearningBayesiannetworks(https://sites.
google.
com/site/ijcai2013bns/slides),2013.
[6]C.
P.
deCamposandQ.
Ji.
EfcientstructurelearningofBayesiannetworksusingconstraints.
JournalofMachineLearningResearch,12:663–689,2011.
[7]C.
P.
deCampos,Z.
Zeng,andQ.
Ji.
StructurelearningofBayesiannetworksusingconstraints.
InProceedingsofthe26stAnnualInternationalConferenceonMachineLearning,ICML-09,pages113–120,2009.
[8]J.
V.
HaarenandJ.
Davis.
Markovnetworkstructurelearning:Arandomizedfeaturegenerationapproach.
InProceedingsofthe26stAAAIConferenceonArticialIntelligence,2012.
[9]D.
Heckerman,D.
Geiger,andD.
M.
Chickering.
LearningBayesiannetworks:Thecombina-tionofknowledgeandstatisticaldata.
MachineLearning,20:197–243,1995.
[10]T.
Jaakkola,D.
Sontag,A.
Globerson,andM.
Meila.
LearningBayesianNetworkStructureusingLPRelaxations.
InProceedingsofthe13stInternationalConferenceonArticialIntel-ligenceandStatistics,AISTATS-10,pages358–365,2010.
[11]M.
Koivisto.
ParentassignmentishardfortheMDL,AIC,andNMLcosts.
InProceedingsofthe19stannualconferenceonLearningTheory,pages289–303.
Springer-Verlag,2006.
[12]M.
KoivistoandK.
Sood.
ExactBayesianStructureDiscoveryinBayesianNetworks.
JournalofMachineLearningResearch,5:549–573,2004.
[13]D.
LowdandJ.
Davis.
LearningMarkovnetworkstructurewithdecisiontrees.
InGeoffreyI.
Webb,BingLiu0001,ChengqiZhang,DimitriosGunopulos,andXindongWu,editors,Pro-ceedingsofthe10stInt.
ConferenceonDataMining(ICDM2010),pages334–343,2010.
[14]W.
J.
McGill.
Multivariateinformationtransmission.
Psychometrika,19(2):97–116,1954.
[15]A.
MooreandW.
Wong.
Optimalreinsertion:AnewsearchoperatorforacceleratedandmoreaccurateBayesiannetworkstructurelearning.
InT.
FawcettandN.
Mishra,editors,Proceedingsofthe20stInternationalConferenceonMachineLearning,ICML-03,pages552–559,MenloPark,California,August2003.
AAAIPress.
[16]A.
E.
Raftery.
Bayesianmodelselectioninsocialresearch.
Sociologicalmethodology,25:111–164,1995.
[17]T.
SilanderandP.
Myllymaki.
AsimpleapproachforndingthegloballyoptimalBayesiannetworkstructure.
InProceedingsofthe22ndConferenceonUncertaintyinArticialIntelli-gence,UAI-06,pages445–452,2006.
[18]M.
TeyssierandD.
Koller.
Ordering-basedsearch:Asimpleandeffectivealgorithmforlearn-ingBayesiannetworks.
InProceedingsofthe21stConferenceonUncertaintyinArticialIntelligence,UAI-05,pages584–590,2005.
[19]C.
YuanandB.
Malone.
AnimprovedadmissibleheuristicforlearningoptimalBayesiannetworks.
InProceedingsofthe28stConferenceonUncertaintyinArticialIntelligence,UAI-12,2012.
[20]C.
YuanandB.
Malone.
LearningoptimalBayesiannetworks:Ashortestpathperspective.
JournalofArticialIntelligenceResearch,48:23–65,2013.
9
- proposedto相关文档
- 投标destoon
- 新站Destoon模版标签调用代码大集合
- 调用destoon标签大全开发文档
- 调用destoon官方标签大全
- 模板destoon二次开发模板和调用语法参考
- 分类destoon调用当前栏目分类及子分类和三级分类的方法
Dynadot多种后缀优惠域名优惠码 ,.COM域名注册$6.99
Dynadot 是一家非常靠谱的域名注册商家,老唐也从来不会掩饰对其的喜爱,目前我个人大部分域名都在 Dynadot,还有一小部分在 NameCheap 和腾讯云。本文分享一下 Dynadot 最新域名优惠码,包括 .COM,.NET 等主流后缀的优惠码,以及一些新顶级后缀的优惠。对于域名优惠,NameCheap 的新后缀促销比较多,而 Dynadot 则是对于主流后缀的促销比较多,所以可以各取所...
享有云:美国BGP云服务器低至20元/月起,首月打折;香港2核2G2M仅50元/月起
享有云怎么样?享有云是一家新的国内云服务器商家,目前提供国内、香港及海外地区的云服务器,拥有多线路如:BGP线路、CN2线路、高防等云服务器,并且提供稳定、安全、弹性、高性能的云端计算服务,实时满足您的多样性业务需求。目前,美国bgp云服务器,5M带宽,低至20元/月起,270元/年起,首月打折;香港2核2G2M仅50元/月起,450元/年起!点击进入:享有云官方网站地址享有云优惠活动:一、美国B...
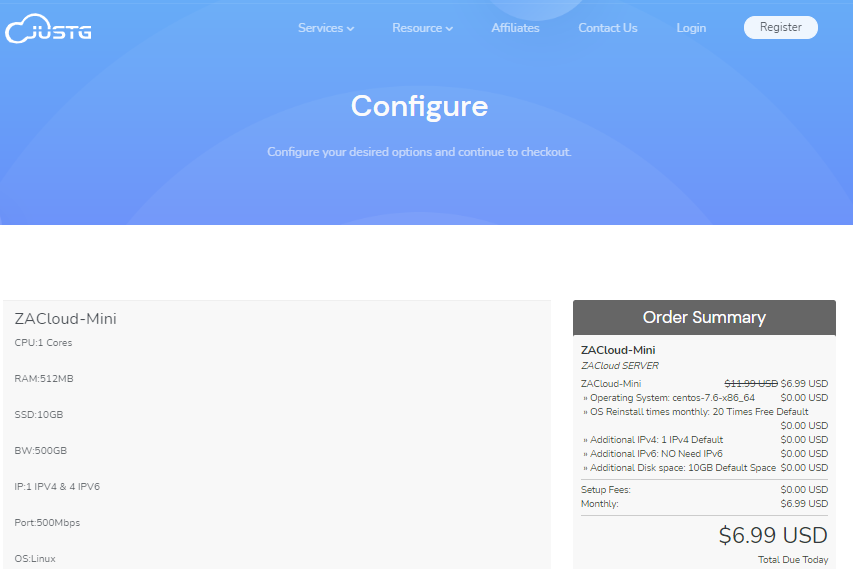
JUSTG(5.99美元/月)最新5折优惠,KVM虚拟虚拟512Mkvm路线
Justg是一家俄罗斯VPS云服务器提供商,主要提供南非地区的VPS服务器产品,CN2高质量线路网络,100Mbps带宽,自带一个IPv4和8个IPv6,线路质量还不错,主要是用户较少,带宽使用率不高,比较空闲,不拥挤,比较适合面向非洲、欧美的用户业务需求,也适合追求速度快又需要冷门的朋友。justg的俄罗斯VPS云服务器位于莫斯科机房,到美国和中国速度都非常不错,到欧洲的平均延迟时间为40毫秒,...
destoon为你推荐
-
destoondestoon多少人是从PHP168过来的啊?Destoon的B2B很好,强烈支持你们wordpress模板我在wordpress模板下载了一套模板,做了www.xuanqianbao.com这个站,模板的原站是www.rrzdm.com.一样的模板,我在文件在插入图片,却不能在首页显示,他的网站却可以.直linux防火墙设置怎样用iptables配置好Linux防火墙?新iphone也将禁售现在2017年iPhone6s还有多久会被淘汰360公司迁至天津请问360公司的全称是什么?人人视频总部基地落户重庆重庆影视公司怎么选择?泉州商标注册泉州商标注册找什么公司?爱买网超谁有http://www.25j58.com爱网购吧网站简介?curl扩展如何增加mysqli扩展zhuo爱大涿爱— 金鱼花火 、 歌词给我翻译过来。!